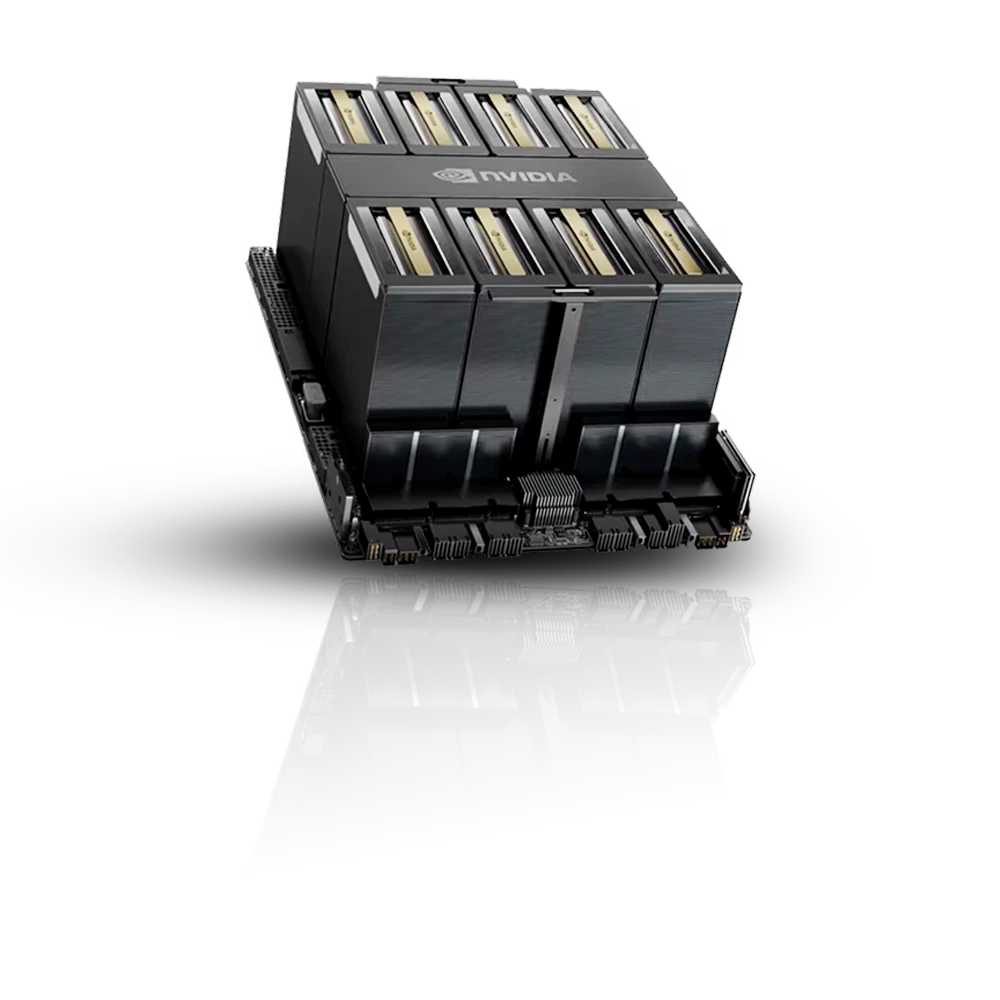
Agentic workloads differ from typical chat inference in one key way: a single user request can trigger a chain of many model calls, as the agent reasons, calls tools, reads results, and reasons again before producing a final answer. This makes latency per call compound quickly, since a 5-step agentic task with 2-second-per-call latency takes 10 seconds end to end even before accounting for tool execution time. H100's combination of FP8 throughput and strong single-request latency makes it well suited to agentic serving, where the priority is often fast, consistent per-call response time over raw batch throughput, and where request patterns are bursty and unpredictable rather than steady. H200, B200 and B300 for AI agents are worth the premium specifically for long-running sessions with heavy accumulated context. GB300 for AI agents sits at the top of the range as rack-scale Blackwell Ultra for the largest workloads.
What makes agentic workloads distinct is the multi-step nature of a single logical task: an agent might call the model to decide which tool to use, call the model again to formulate the tool's arguments, execute the tool, then call the model a third time to interpret the result and decide the next step. Each of these calls adds latency, so the per-call response time matters more for agents than it does for a single chat response, where users tolerate a bit more variance. H100's FP8 throughput helps keep per-call latency low even under concurrent agentic load, and MIG partitioning lets a single card serve several lower-priority agentic workloads alongside latency-sensitive ones without needing dedicated hardware for each. Because agentic request volume is often bursty and hard to predict in advance, serving infrastructure that can flex capacity up and down matters more here than for steadier workloads like batch inference.
Agentic applications are often latency-sensitive end-to-end products, so placing GPU capacity close to your users matters. See H100 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


