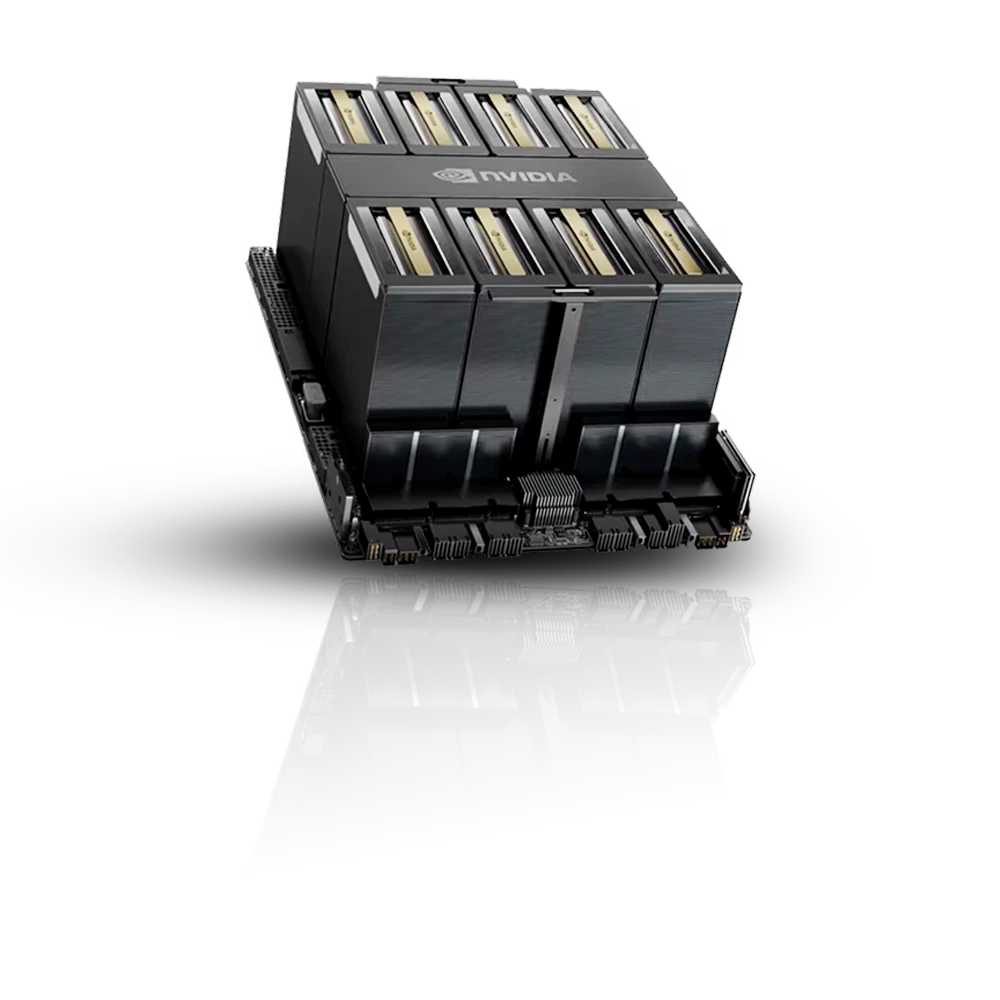
Most agentic workloads never need B300, since typical multi-step tasks fit comfortably on H100 and even heavy context-accumulation cases are well served by H200 or B200. B300 matters for the narrowest slice of agentic deployments: sessions accumulating context so extensive that even B200's 192GB becomes a real constraint, where B300's 288GB and higher raw compute keep per-call latency low at a scale no earlier generation comfortably reaches. Full NVIDIA B300 specs are available on request. B200, H200 and H100 for AI agents remain the practical default for the overwhelming majority of agentic workloads today. GB300 for AI agents takes the same silicon to rack scale, for workloads that need one memory pool across 72 GPUs.
The honest answer for agentic workloads is that almost none of them need B300: a typical multi-step task fits comfortably on H100, and even substantial context accumulation across a long-running session is well served by H200 or B200's existing memory headroom. B300's case narrows to the most extreme end of agentic deployment, sessions accumulating context so extensive that even B200's 192GB becomes a genuine constraint, which describes a very small fraction of real agentic workloads today. For that narrow slice, B300's 288GB extends how much accumulated state an agent can hold beyond any earlier generation, and its higher raw compute keeps per-call latency low even at that extreme scale. For the overwhelming majority of agentic deployments, the practical guidance is unchanged from H100: moderate context and typical session lengths don't justify B300's premium, narrower availability, or higher power requirements.
Agentic applications are often latency-sensitive end-to-end products, so placing GPU capacity close to your users matters. See B300 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


