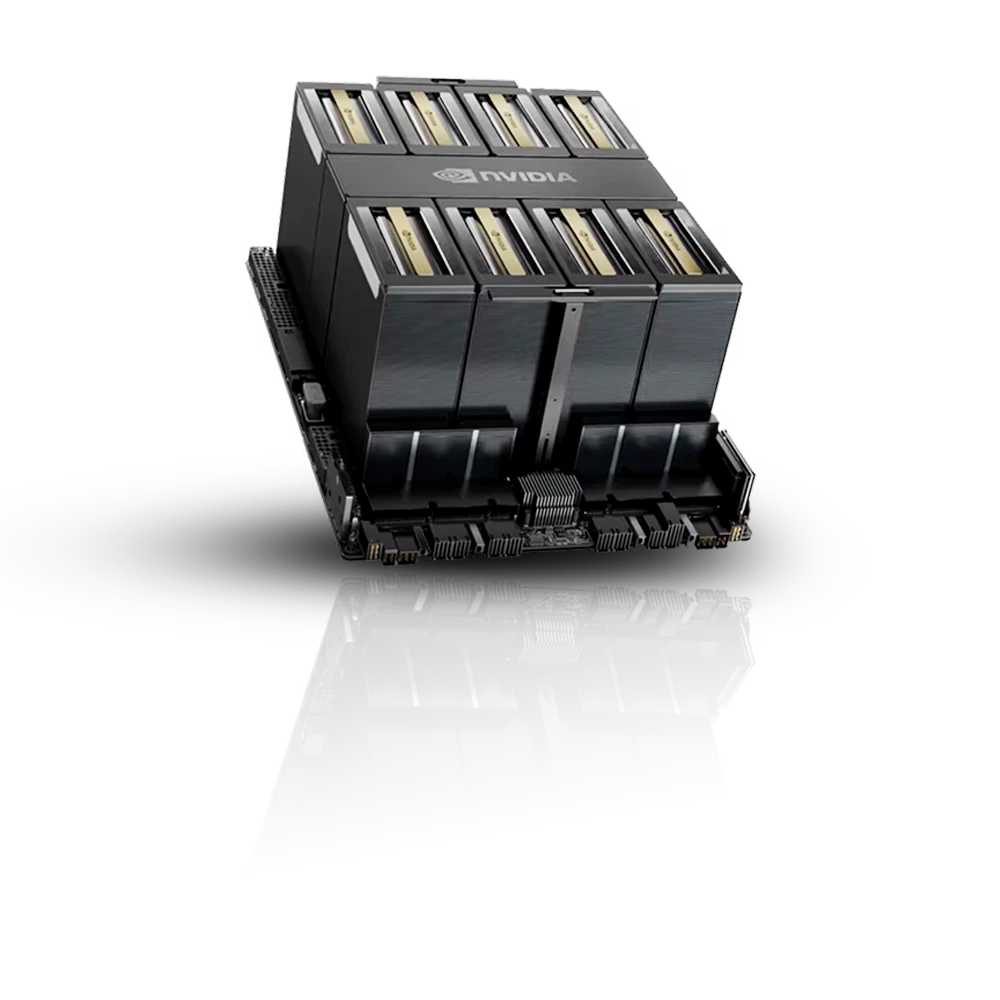
Most agentic workloads don't need B200's extra capability, since a typical multi-step task with moderate context fits comfortably on H100 or even an entry point as modest as a single H200. Where B200 genuinely helps is agents accumulating very large context across long-running sessions, extensive tool-call histories, large retrieved documents, beyond what even H200's 141GB comfortably holds, plus B200's raw compute advantage keeps per-call latency low even at that scale. Full NVIDIA B200 specs are available on request. H200 and H100 for AI agents remain the practical default for the overwhelming majority of agentic workloads today, and B300 extends B200's ceiling further still for the most extreme context accumulation.
Most agentic workloads don't push against memory limits at all, since a typical multi-step task with a handful of tool calls comfortably fits within H100's 80GB, let alone H200's 141GB. B200's case strengthens specifically for agents accumulating genuinely large context over very long-running sessions, extensive conversation history, many tool-call outputs, or large retrieved documents compounding over time, where even H200's extra headroom over H100 eventually gets exhausted. For these exceptionally long or context-heavy agentic deployments, B200's 192GB extends how much accumulated state an agent can hold, and its raw compute advantage keeps per-call latency low even as that context grows substantial, which matters given agentic tasks already compound latency across sequential model calls. For the large majority of agentic workloads with moderate context and typical session lengths, H100 or H200 remain the more practical choice.
Agentic applications are often latency-sensitive end-to-end products, so placing GPU capacity close to your users matters. See B200 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


