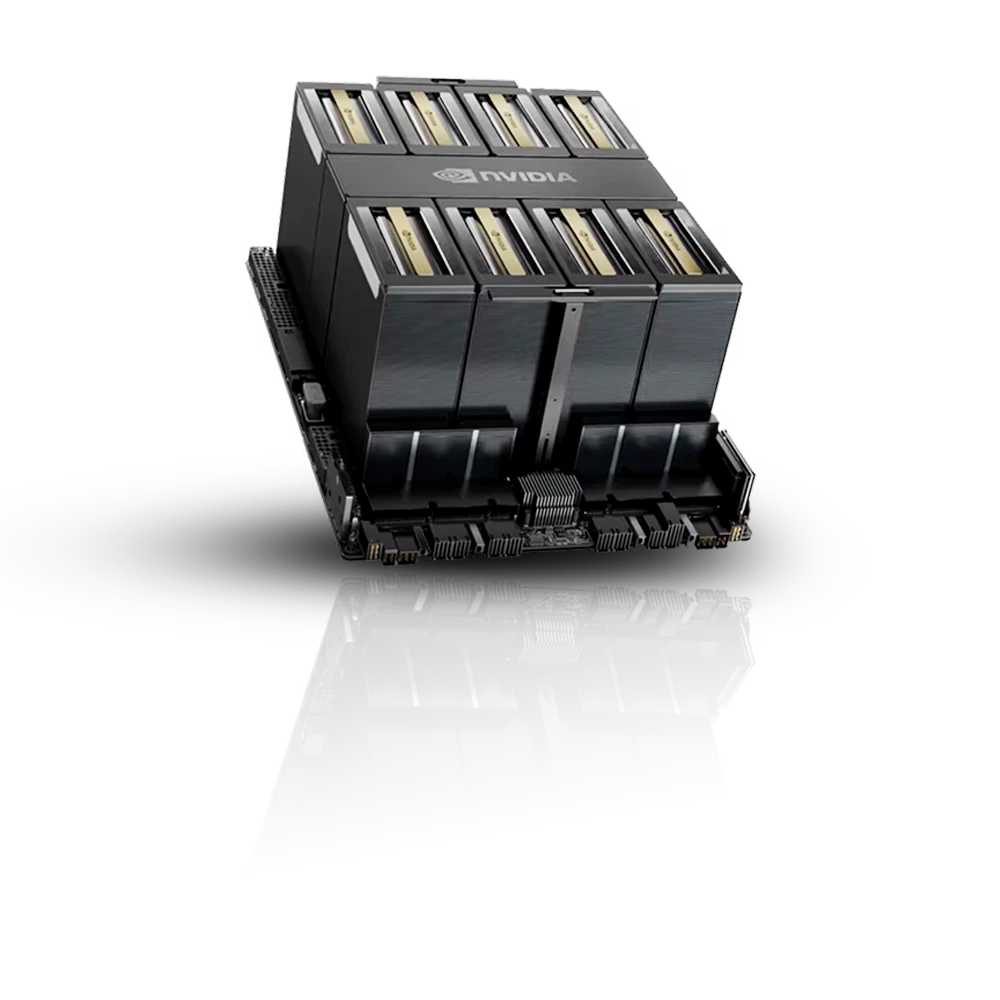
GB300 NVL72 is rack-scale Blackwell Ultra: 72 GPUs and 36 Grace CPUs in a single NVLink domain, with 288GB of HBM3e per GPU and 20TB in aggregate. For inference, that matters when a model, or its KV cache at long context, is too large for one node and would otherwise be sharded across slower links. It is the same silicon as B300 sold as a whole rack, so the question is rarely which chip and usually whether your serving setup needs the rack. Tracked on-demand GB300 price per hour spans roughly $4.00 to $18.00 per GPU on a thin provider set. Full NVIDIA GB300 NVL72 specs are available on request. B300, B200 and H200 for LLM inference remain the more available options for models that fit on a single node.
GB300 NVL72 is Blackwell Ultra deployed as a full rack: 72 GPUs and 36 Grace CPUs in a single NVLink domain, 288GB of HBM3e per GPU and 20TB in aggregate. It is the same silicon as B300, so the real decision is about form factor, not the chip. For inference, the rack matters when a model or its KV cache at long context spans many GPUs and would otherwise cross slower node-to-node links. NVFP4, the native 4-bit format on Blackwell Ultra, follows the same adoption path as FP4 on B200, with most production traffic today still on FP8 or BF16. For inference that fits comfortably on B300, B200 or H200 nodes, the rack adds cost without a matching benefit, and at roughly 135-140kW per rack its supply sits with a limited set of operators, making it a deliberate choice for the largest serving workloads rather than a default upgrade.
GB300 inference is placement-sensitive: rack-scale power and liquid cooling make confirming real in-country supply matter more than for any single-card generation. See GB300 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


