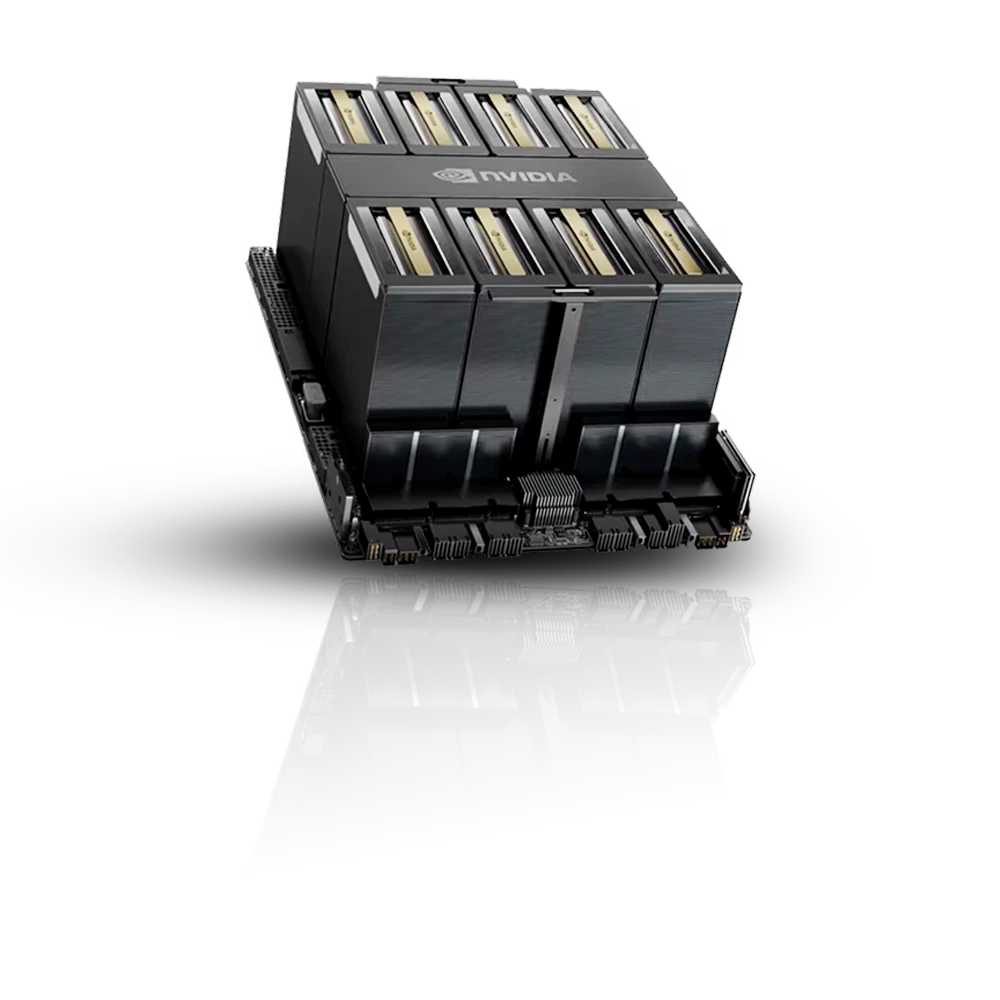
B200 is a genuine architecture change from H100 and H200, not just a memory bump: it's Blackwell rather than Hopper, and its headline capability for inference is native FP4 precision, a 4-bit floating point format neither Hopper-generation card supports. Real-world benchmarks put B200 at roughly 2.5x H100's inference throughput at comparable precision, and 192GB of HBM3e gives even more headroom than H200's 141GB for large models and long context. The tradeoff is real: B200 draws roughly 1,000 watts per GPU against H100 and H200's 700W, which means liquid cooling rather than air, and in several markets B200 supply is genuinely thinner than the established Hopper-generation footprint. Full NVIDIA B200 specs and server configuration options are available on request. H200 and H100 for LLM inference remain the more available, established options for most workloads today, and B300 extends B200's memory ceiling further still for the largest frontier models.
B200 is built on Blackwell rather than Hopper, and the most consequential change for inference is native FP4 precision: a 4-bit floating point format that roughly doubles achievable throughput again over FP8 for models and serving engines built to use it, on top of Blackwell's raw compute advantage over Hopper. Combined, this puts B200 at roughly 2.5x H100's inference throughput at comparable precision. The 192GB of HBM3e, more than H200's 141GB, extends how large a model or how long a context can run on a single card even further than H200 already does. None of this comes free: B200 draws roughly 1,000 watts per GPU against H100 and H200's 700W, requiring liquid cooling rather than air, and that facility requirement is part of why B200 supply genuinely trails H100 and H200 in several markets today as operators retrofit for the higher draw.
B200 inference is placement-sensitive: prompts and responses are often personal data, so jurisdiction matters as much as latency, and B200's power draw makes confirming real in-country supply worth checking. See B200 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


