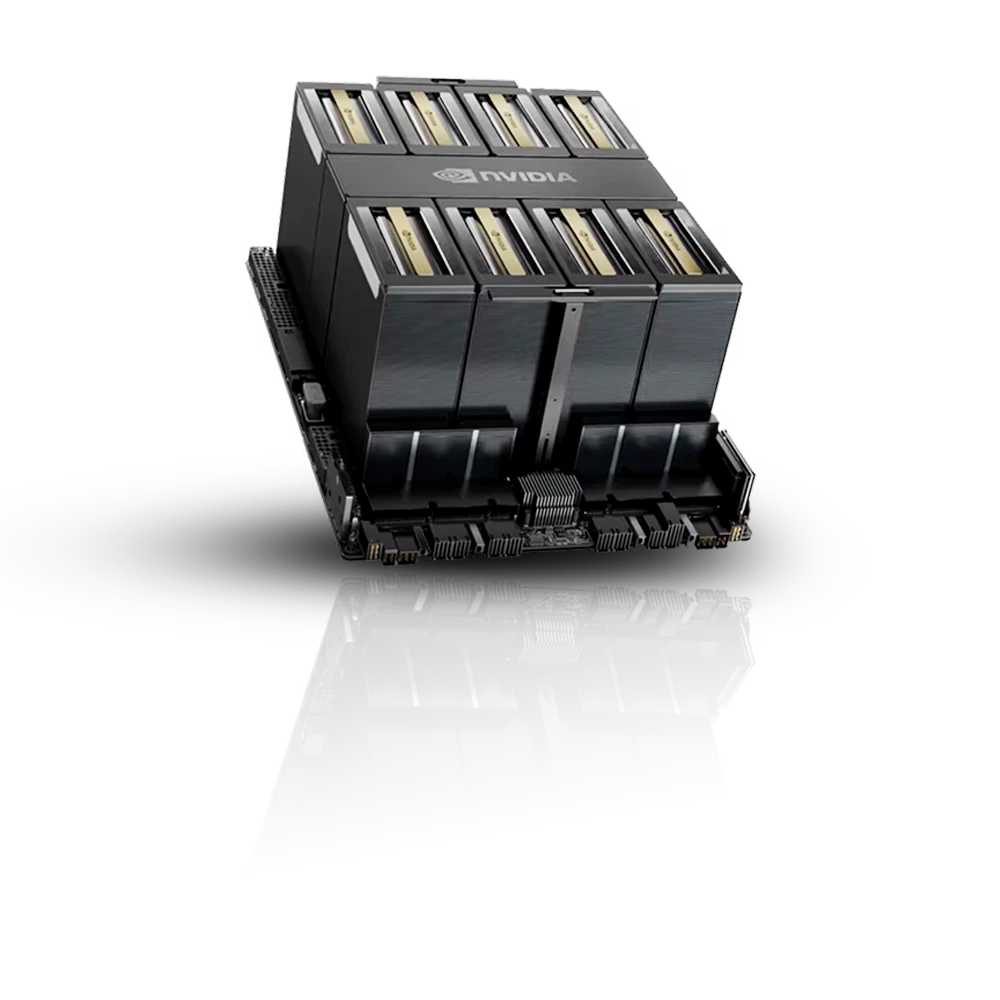
B300 extends the same Blackwell story B200 started, further in both directions: 288GB of HBM3e against B200's 192GB, and roughly 1,400 watts per GPU against B200's roughly 1,000W. For inference specifically, that memory ceiling matters most for the largest frontier models and the longest context windows, where even B200's 192GB can be the binding constraint. NVFP4, NVIDIA's native 4-bit format on Blackwell Ultra, carries the same throughput story as B200's FP4: a real gain once serving engines fully support it, with most production traffic today still running FP8 or BF16. Full NVIDIA B300 specs are available on request. B200, H200 and H100 for LLM inference remain the more available, established options for most workloads today. GB300 for LLM inference takes the same silicon to rack scale, for workloads that need one memory pool across 72 GPUs.
B300 is Blackwell Ultra, an incremental step past B200 on the same architecture rather than a new one, and the gains land in the same two places: more memory, 288GB of HBM3e against B200's 192GB, and higher compute, at the cost of roughly 1,400 watts per GPU against B200's roughly 1,000W. For inference, this combination matters specifically at the frontier: the largest models, the longest context windows, and the highest-throughput serving where even B200's ceiling becomes the binding constraint. NVFP4, the native 4-bit format on Blackwell Ultra, follows the same adoption path FP8 did on H100 and FP4 did on B200, real throughput gains once serving engines catch up, with most production traffic today still running at FP8 or BF16. For inference workloads that already run comfortably on B200, H200 or H100, B300 offers no corresponding benefit, and its narrower availability (given facility requirements that trail even B200's) makes it a deliberate choice for frontier-scale needs rather than a default upgrade path.
B300 inference is placement-sensitive, and its power draw makes confirming real in-country supply more important than for any earlier generation. See B300 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


