B300
UK
{"@context":"https://schema.org","@graph":[{"@type":"Service","@id":"https://gpuaas.com/gpu/b300-fine-tuning#service","name":"B300 for Fine-tuning","provider":{"@type":"Organization","name":"GPUaaS.com","url":"https://gpuaas.com"},"serviceType":"GPU cloud infrastructure","description":"B300 for fine-tuning: when 288GB matters beyond B200's 192GB, and why earlier generations remain the default for typical LoRA/QLoRA work."},{"@type":"WebPage","@id":"https://gpuaas.com/gpu/b300-fine-tuning#webpage","url":"https://gpuaas.com/gpu/b300-fine-tuning","name":"B300 for Fine-tuning","isPartOf":{"@type":"WebSite","name":"GPUaaS.com","url":"https://gpuaas.com"}},{"@type":"BreadcrumbList","@id":"https://gpuaas.com/gpu/b300-fine-tuning#breadcrumb","itemListElement":[{"@type":"ListItem","position":1,"name":"Home","item":"https://gpuaas.com"},{"@type":"ListItem","position":2,"name":"GPU Cloud","item":"https://gpuaas.com/cluster"},{"@type":"ListItem","position":3,"name":"B300 for Fine-tuning","item":"https://gpuaas.com/gpu/b300-fine-tuning"}]},{"@type":"FAQPage","@id":"https://gpuaas.com/gpu/b300-fine-tuning#faq","mainEntity":[{"@type":"Question","name":"Do I need B300's extra memory for fine-tuning?","acceptedAnswer":{"@type":"Answer","text":"Rarely, for standard LoRA and QLoRA work, since that fits comfortably on H100, H200 or B200 already. B300 matters specifically for full fine-tuning of the largest base models, or QLoRA fine-tuning past what even B200's 192GB comfortably holds."}},{"@type":"Question","name":"When would B300's 288GB matter for fine-tuning?","acceptedAnswer":{"@type":"Answer","text":"This is the clearest case for B300 in fine-tuning: when a base model is too large for even B200's 192GB to handle with QLoRA, it becomes realistic on a single B300's 288GB, avoiding a multi-GPU setup entirely."}},{"@type":"Question","name":"Do fine-tuning frameworks support B300?","acceptedAnswer":{"@type":"Answer","text":"Hugging Face PEFT and Axolotl both support B300, since it's a supported Blackwell Ultra card for these frameworks. No changes to your fine-tuning setup are needed moving from B200, H200 or H100."}},{"@type":"Question","name":"Should I default to an earlier generation or B300 for fine-tuning?","acceptedAnswer":{"@type":"Answer","text":"H100, H200 or B200, for the large majority of fine-tuning work. B300's premium only pays off when your specific base model size genuinely requires more than even B200's 192GB, which is a narrow slice of fine-tuning projects."}},{"@type":"Question","name":"Is B300 harder to find for fine-tuning workloads specifically?","acceptedAnswer":{"@type":"Answer","text":"Narrower than B200 in most markets, given the liquid cooling and power infrastructure B300 requires. For typical fine-tuning work that doesn't need B300's extra memory anyway, this availability gap is one more reason earlier generations remain the simpler choice."}},{"@type":"Question","name":"What's the real NVIDIA B300 rental rate for fine-tuning work?","acceptedAnswer":{"@type":"Answer","text":"B300 median on-demand rate runs $7.50/hr, a real premium over B200's $6.01/hr, H200's $4.40/hr and H100's $3.33/hr median. NVIDIA B300 rental pricing is quoted per enquiry and varies by commitment term, configuration and placement."}}]}]}
GPUAAS.COM · WHOLESALE GPU NETWORK / A HOSTED·AI SERVICE ◆ CAPACITY AVAILABLE · 20+ PARTNERSQUOTES < 24HREV 2026.09
+
+
◆
B300 SXM for fine-tuning
◆ AVAILABLE

B300
for fine-tuning
, at
wholesale price.

B300 SXM from vetted rental partners, for base models beyond what 192GB can hold, at
~30% less than hyperscale. Quotes in under 24 hours.

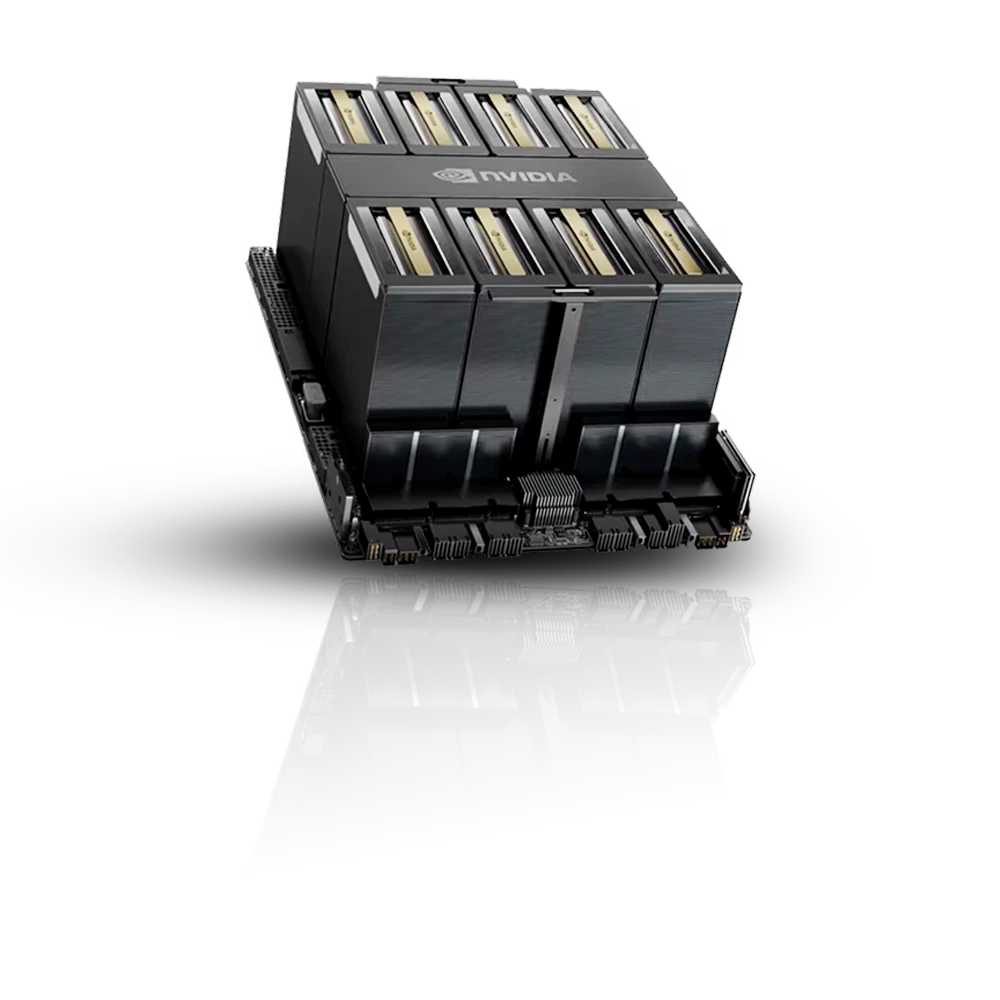
HGX GPU node
GPU generations
8
Architectures
Hopper + Blackwell + Vera Rubin
Vetted partners
20+
Quote turnaround
24 hrs
Commitment
Short / long
QUOTES IN UNDER 24 HOURS VETTED PARTNERS WORLDWIDE SHORT OR LONG TERM COMMITMENT DIRECT OPERATOR CONTRACTS CAPACITY AVAILABLE NOW PLACEMENT YOU SPECIFY
◆ THE SHORT ANSWER

Fine-tuning on B300 follows the exact pattern established by B200: most LoRA and QLoRA work fits comfortably within far less than 288GB, so B300's extra memory matters specifically for full fine-tuning of the largest base models, or QLoRA fine-tuning of models beyond what even B200's 192GB comfortably holds. For the large majority of fine-tuning projects, earlier generations handle the work just as well at a meaningfully lower hourly rate. Full NVIDIA B300 specs are available on request. B200, H200 and H100 for fine-tuning remain the practical default for the large majority of fine-tuning workloads today. GB300 for fine-tuning takes the same silicon to rack scale, for workloads that need one memory pool across 72 GPUs.

+
01
PRICING

What B300 fine-tuning actually costs

B300 median on-demand rate runs $7.50/hr across 11 tracked providers, ranging from $6.50 at the low end to $15.00 for specialist guaranteed-capacity providers. For typical LoRA and QLoRA work, earlier generations' lower rates are usually the better choice. NVIDIA B300 pricing is quoted per enquiry; full NVIDIA B300 specs are available on request.

Market reference as of September 2026, quoted in USD. Actual fine-tuning cost depends heavily on dataset size, number of epochs, and whether you use LoRA/QLoRA versus full fine-tuning.
Wholesale rates through GPUaaS.com are quoted per enquiry and vary by commitment term, configuration and placement.

$0$2.50$5$7.50$10$12.50$15/GPU-HR
Market low, 11 providers tracked
Cheapest tracked B300 SXM on-demand
$6.50
Median on-demand B300 SXM
Median across 11 tracked providers
$7.50
Market high, specialist providers
Premium providers, guaranteed capacity
$15.00
Hyperscaler on-demand
What you pay without a broker
$17.80
◆ GPUaaS.com wholesale
Vetted partners · direct operator contract
quoted per enquiry
B300 MARKET RATES, AUGUST 2026
+
02
◆
Where B300 earns its keep in fine-tuning

What B300 handles well for fine-tuning, and what to watch for.

Fine-tuning's memory needs scale with base model size, and B300's 288GB only becomes the deciding factor once a base model pushes past what even B200's 192GB can handle with QLoRA, which is a genuinely narrow slice of fine-tuning projects. For the large majority of LoRA and QLoRA work, H100, H200 or B200 fine-tune identically at a meaningfully lower hourly rate, since B300 offers no speed advantage for fine-tuning workloads that already fit comfortably within earlier generations' memory. Where B300 does earn its premium is full fine-tuning or QLoRA fine-tuning of the very largest base models, where 288GB avoids a multi-GPU setup that even B200 would otherwise need. Hugging Face PEFT and Axolotl both already support Blackwell Ultra, so adopting B300 for these specific cases requires no change to an existing fine-tuning pipeline.

/01

Base models past 192GB

288GB handles base models beyond what even B200's 192GB can fine-tune with QLoRA, avoiding a multi-GPU setup entirely.
288GB · beyond B200 · largest base models
/02

Standard fine-tuning stays on earlier generations

For typical LoRA and QLoRA work, earlier generations handle it identically at a meaningfully lower hourly rate.
earlier generations sufficient · typical work · lower cost
/03

Same fine-tuning frameworks

Hugging Face PEFT and Axolotl setups carry over to B300 without changes, since it's a supported Blackwell Ultra card.
PEFT · Axolotl · drop-in
/04

Check real availability first

Liquid cooling and power requirements mean B300 availability trails even B200 in several markets.
availability · liquid cooling · confirm supply
+
03
◆ LIVE NETWORK · 12 LOCATIONS

B300 capacity worldwide, in the location you need.

Fine-tuning runs often use proprietary or sensitive training data, so where the GPU physically sits can matter as much as its specs. See B300 availability by country below.

Read the full guide to GPU cloud in this location →
8
GPU GENERATIONS
20+
VETTED PARTNERS
12
PLACEMENT OPTIONS
24h
QUOTE TURNAROUND
◆ USA◆ CAN◆ UK◆ DEU◆ FRA◆ NLD◆ UAE◆ SAU◆ IND◆ SGP◆ JPN◆ AUS

Every location links to its own page. Click through for local pricing and specs.

04
◆ COST COMPARISON

See how much you save at scale

Wholesale rates against cloud list price for a 64-GPU cluster.

CLUSTER SIZE
8 GPU Servers
64 × GPUS · 730 HRS/MO
ASSUMPTIONS · BLENDED $6.00/GPU-HR · INDICATIVE ONLY
SOURCEEST. MONTHLYVS GPUAAS
Retail cloud
On-demand list price · reserved discounts require lock-in
~$280k
+$84k
Direct datacentre negotiation
Long-term commitment · slow procurement cycle
~$230k
+$34k
◆ BEST VALUE
GPUaaS.com wholesale
Vetted partners · direct operator contract · quotes in 24 hours
~$196k
SAVE ~$84k/MO
Need single-GPU compute? packet.ai has you covered.
+
05
◆ HOW IT WORKS

A matchmaker, not a marketplace.

We connect you to our vetted partners. You contract directly with the operator running your nodes.

STEP 01/4
01

Tell us the requirement

GPU model, count, placement and timeline. Add workload detail if you have it.

STEP 02/4
02

We match capacity

We find vetted partners with capacity that fits, in the jurisdiction you need.

STEP 03/4
03

Quotes in 24 hours

Real quotes from partners who hold the capacity, not listings that may not exist.

STEP 04/4
04

Contract and provision

You contract directly with the operator. We smooth the provisioning process.

Get a quote
Request wholesale rates
in under 24 hours.

Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

◆Quotes in under 24 hours
◆Direct contact with operators
◆Vetted partners, matched to your requirement
◆20+ vetted providers · 12 locations
1
ESSENTIALS
2
OPTIONAL
Contact
Full Name *
Business Email *
Organization *
Preferred Location *
Your Region *
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
GPU Requirements
GPU Model *
PRE-SELECTED
Number of GPUs *
Individual GPU count. 1 node = 8 GPUs.
Get the Best Deal→
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
+
06
◆ FAQ

Frequently Asked Questions

Q1
Do I need B300's extra memory for fine-tuning?

Rarely, for standard LoRA and QLoRA work, since that fits comfortably on H100, H200 or B200 already. B300 matters specifically for full fine-tuning of the largest base models, or QLoRA fine-tuning past what even B200's 192GB comfortably holds.

Q2
When would B300's 288GB matter for fine-tuning?

This is the clearest case for B300 in fine-tuning: when a base model is too large for even B200's 192GB to handle with QLoRA, it becomes realistic on a single B300's 288GB, avoiding a multi-GPU setup entirely.

Q3
Do fine-tuning frameworks support B300?

Hugging Face PEFT and Axolotl both support B300, since it's a supported Blackwell Ultra card for these frameworks. No changes to your fine-tuning setup are needed moving from B200, H200 or H100.

Q4
Should I default to an earlier generation or B300 for fine-tuning?

H100, H200 or B200, for the large majority of fine-tuning work. B300's premium only pays off when your specific base model size genuinely requires more than even B200's 192GB, which is a narrow slice of fine-tuning projects.

Q5
Is B300 harder to find for fine-tuning workloads specifically?

Narrower than B200 in most markets, given the liquid cooling and power infrastructure B300 requires. For typical fine-tuning work that doesn't need B300's extra memory anyway, this availability gap is one more reason earlier generations remain the simpler choice.

Q6
What's the real NVIDIA B300 rental rate for fine-tuning work?

B300 median on-demand rate runs $7.50/hr, a real premium over B200's $6.01/hr, H200's $4.40/hr and H100's $3.33/hr median. NVIDIA B300 rental pricing is quoted per enquiry and varies by commitment term, configuration and placement.