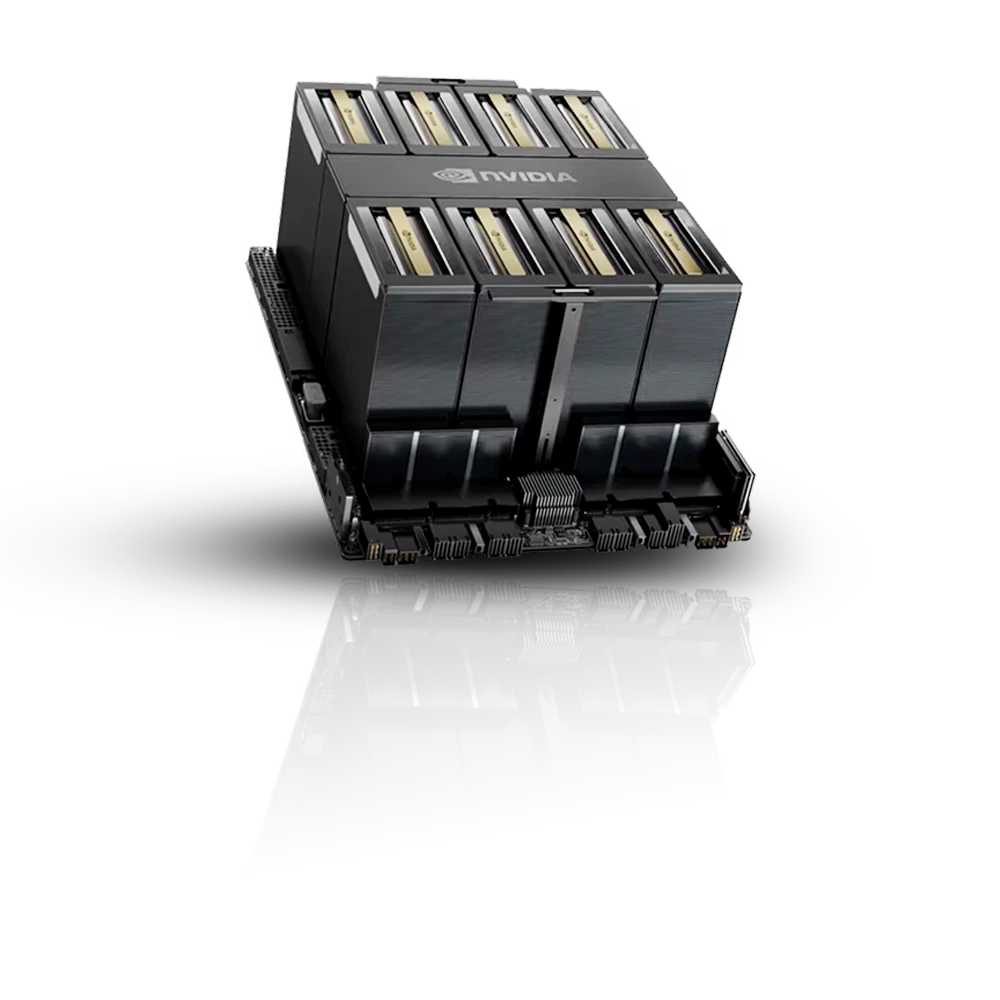
B200
UK
{"@context": "https://schema.org", "@graph": [{"@type": "Service", "@id": "https://gpuaas.com/gpu/b200-fine-tuning#service", "name": "B200 for Fine-tuning", "provider": {"@type": "Organization", "name": "GPUaaS.com", "url": "https://gpuaas.com"}, "serviceType": "GPU cloud infrastructure", "description": "B200 for fine-tuning: when 192GB matters beyond H200's 141GB, and why H100 or H200 remains the default for typical LoRA/QLoRA work. From vetted partners."}, {"@type": "WebPage", "@id": "https://gpuaas.com/gpu/b200-fine-tuning#webpage", "url": "https://gpuaas.com/gpu/b200-fine-tuning", "name": "B200 for Fine-tuning", "isPartOf": {"@type": "WebSite", "name": "GPUaaS.com", "url": "https://gpuaas.com"}}, {"@type": "BreadcrumbList", "@id": "https://gpuaas.com/gpu/b200-fine-tuning#breadcrumb", "itemListElement": [{"@type": "ListItem", "position": 1, "name": "Home", "item": "https://gpuaas.com"}, {"@type": "ListItem", "position": 2, "name": "GPU Cloud", "item": "https://gpuaas.com/cluster"}, {"@type": "ListItem", "position": 3, "name": "B200 for Fine-tuning", "item": "https://gpuaas.com/gpu/b200-fine-tuning"}]}, {"@type": "FAQPage", "@id": "https://gpuaas.com/gpu/b200-fine-tuning#faq", "mainEntity": [{"@type": "Question", "name": "Do I need B200's extra memory for fine-tuning?", "acceptedAnswer": {"@type": "Answer", "text": "Rarely, for standard LoRA and QLoRA work on models up to 70B or so, since those fit comfortably on H100 or H200 already. B200 matters specifically for full fine-tuning of the largest base models, or QLoRA fine-tuning past what H200's 141GB comfortably holds."}}, {"@type": "Question", "name": "When would B200's 192GB matter for fine-tuning?", "acceptedAnswer": {"@type": "Answer", "text": "This is the clearest case for B200 in fine-tuning: when a base model is too large for even H200's 141GB to handle with QLoRA, it becomes realistic on a single B200's 192GB, avoiding a multi-GPU setup entirely."}}, {"@type": "Question", "name": "Do fine-tuning frameworks support B200?", "acceptedAnswer": {"@type": "Answer", "text": "Hugging Face PEFT and Axolotl both support B200, since it's a supported Blackwell-generation card for these frameworks. No changes to your fine-tuning setup are needed moving from H100 or H200."}}, {"@type": "Question", "name": "Should I default to H100, H200 or B200 for fine-tuning?", "acceptedAnswer": {"@type": "Answer", "text": "H100 or H200, for the large majority of fine-tuning work. B200's premium only pays off when your specific base model size genuinely requires more than 141GB."}}, {"@type": "Question", "name": "Is B200 harder to find for fine-tuning workloads specifically?", "acceptedAnswer": {"@type": "Answer", "text": "In several markets, yes, given the liquid cooling and power infrastructure B200 requires."}}]}]}
GPUAAS.COM · WHOLESALE GPU NETWORK / A HOSTED·AI SERVICE ◆ CAPACITY AVAILABLE · 20+ PARTNERSQUOTES < 24HREV 2026.09
+
+
◆
B200 SXM for fine-tuning
◆ AVAILABLE

B200
for fine-tuning
, at
wholesale price.

B200 SXM rental from vetted partners, for base models beyond what 141GB can hold, at
~30% less than hyperscale. Quotes in under 24 hours.

HGX GPU node
GPU generations
8
Architectures
Hopper + Blackwell + Vera Rubin
Vetted partners
20+
Quote turnaround
24 hrs
Commitment
Short / long
QUOTES IN UNDER 24 HOURS VETTED PARTNERS WORLDWIDE SHORT OR LONG TERM COMMITMENT DIRECT OPERATOR CONTRACTS CAPACITY AVAILABLE NOW PLACEMENT YOU SPECIFY
◆ THE SHORT ANSWER

Fine-tuning on B200 follows the same LoRA and QLoRA-first approach as H100 and H200, since most fine-tuning workloads already fit comfortably within far less than 192GB and don't need the extra memory. Where B200 genuinely helps is full fine-tuning of larger base models, or QLoRA fine-tuning of models even larger than the 70B that already fits on a single H100: 192GB gives enough headroom to fine-tune base models well past what H200's 141GB can handle. For most teams fine-tuning 7B-70B models with LoRA or QLoRA, H100 or H200 remain the more cost-effective choice, and the same frameworks (Hugging Face PEFT, Axolotl) carry over to B200 without any changes. H100 and H200 for fine-tuning are the practical default for LoRA and QLoRA work at typical model sizes, and B300 extends B200's ceiling further still for base models beyond 192GB.

+
01
PRICING

What B200 fine-tuning actually costs

B200 median on-demand rate runs $6.01/hr across 17 tracked providers, ranging from $3.75 at the low end to $10.41 for specialist guaranteed-capacity providers. For typical LoRA and QLoRA work, H100 or H200's lower rate is usually the better choice. NVIDIA B200 pricing is quoted per enquiry; full NVIDIA B200 specs are available on request.

Market reference as of September 2026, quoted in USD. Actual fine-tuning cost depends heavily on dataset size, number of epochs, and whether you use LoRA/QLoRA versus full fine-tuning.
Wholesale rates through GPUaaS.com are quoted per enquiry and vary by commitment term, configuration and placement.

$0$2.50$5$7.50$10$12.50$15/GPU-HR
Market low, 17 providers tracked
Cheapest tracked B200 SXM on-demand
$3.75
Median on-demand B200 SXM
Median across 17 tracked providers
$6.01
Market high, specialist providers
Premium providers, guaranteed capacity
$10.41
Hyperscaler on-demand
What you pay without a broker
$16.11
◆ GPUaaS.com wholesale
Vetted partners · direct operator contract
quoted per enquiry
B200 MARKET RATES, AUGUST 2026
+
02
◆
Where B200 earns its keep in fine-tuning

What B200 handles well for fine-tuning, and what to watch for.

Fine-tuning's memory needs scale with base model size, and B200's 192GB only becomes the deciding factor once a base model pushes past what even H200's 141GB can handle with QLoRA, which is a genuinely narrow slice of fine-tuning projects. For the large majority of LoRA and QLoRA work on 7B-70B models, H100 or H200 fine-tune identically at a meaningfully lower hourly rate, since B200 offers no speed advantage for fine-tuning workloads that already fit comfortably within Hopper-generation memory. Where B200 does earn its premium is full fine-tuning or QLoRA fine-tuning of the very largest base models, where 192GB avoids a multi-GPU setup that even H200 would otherwise need. Hugging Face PEFT and Axolotl both already support B200, so adopting it for these specific cases requires no change to an existing fine-tuning pipeline.

/01

Base models past 141GB

192GB handles base models beyond what even H200's 141GB can fine-tune with QLoRA, avoiding a multi-GPU setup entirely.
192GB · beyond H200 · largest base models
/02

Standard fine-tuning stays on Hopper

For typical 7B-70B LoRA and QLoRA work, H100 or H200 handle it identically at a meaningfully lower hourly rate.
H100/H200 sufficient · typical work · lower cost
/03

Same fine-tuning frameworks

Hugging Face PEFT and Axolotl setups carry over to B200 without changes, since it's a supported Blackwell-generation card.
PEFT · Axolotl · drop-in
/04

Check real availability first

Liquid cooling and power requirements mean B200 availability trails H100 and H200 in several markets, worth confirming before planning around it.
availability · liquid cooling · confirm supply
+
03
◆ LIVE NETWORK · 12 LOCATIONS

B200 capacity worldwide, in the location you need.

Fine-tuning runs often use proprietary or sensitive training data, so where the GPU physically sits can matter as much as its specs. See B200 availability by country below.

Read the full guide to GPU cloud in this location →
8
GPU GENERATIONS
20+
VETTED PARTNERS
12
PLACEMENT OPTIONS
24h
QUOTE TURNAROUND
◆ USA◆ CAN◆ UK◆ DEU◆ FRA◆ NLD◆ UAE◆ SAU◆ IND◆ SGP◆ JPN◆ AUS

Every location links to its own page. Click through for local pricing and specs.

04
◆ COST COMPARISON

See how much you save at scale

Wholesale rates against cloud list price for a 64-GPU cluster.

CLUSTER SIZE
8 GPU Servers
64 × GPUS · 730 HRS/MO
ASSUMPTIONS · BLENDED $6.00/GPU-HR · INDICATIVE ONLY
SOURCEEST. MONTHLYVS GPUAAS
Retail cloud
On-demand list price · reserved discounts require lock-in
~$280k
+$84k
Direct datacentre negotiation
Long-term commitment · slow procurement cycle
~$230k
+$34k
◆ BEST VALUE
GPUaaS.com wholesale
Vetted partners · direct operator contract · quotes in 24 hours
~$196k
SAVE ~$84k/MO
Need single-GPU compute? packet.ai has you covered.
+
05
◆ HOW IT WORKS

A matchmaker, not a marketplace.

We connect you to our vetted partners. You contract directly with the operator running your nodes.

STEP 01/4
01

Tell us the requirement

GPU model, count, placement and timeline. Add workload detail if you have it.

STEP 02/4
02

We match capacity

We find vetted partners with capacity that fits, in the jurisdiction you need.

STEP 03/4
03

Quotes in 24 hours

Real quotes from partners who hold the capacity, not listings that may not exist.

STEP 04/4
04

Contract and provision

You contract directly with the operator. We smooth the provisioning process.

Get a quote
Request wholesale rates
in under 24 hours.

Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

◆Quotes in under 24 hours
◆Direct contact with operators
◆Vetted partners, matched to your requirement
◆20+ vetted providers · 12 locations
1
ESSENTIALS
2
OPTIONAL
Contact
Full Name *
Business Email *
Organization *
Preferred Location *
Your Region *
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
GPU Requirements
GPU Model *
PRE-SELECTED
Number of GPUs *
Individual GPU count. 1 node = 8 GPUs.
Get the Best Deal→
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
+
06
◆ FAQ

Frequently Asked Questions

Q1
Do I need B200's extra memory for fine-tuning?

Rarely, for standard LoRA and QLoRA work on models up to 70B or so, since those fit comfortably on H100 or H200 already. B200 matters specifically for full fine-tuning of the largest base models, or QLoRA fine-tuning past what H200's 141GB comfortably holds.

Q2
When would B200's 192GB matter for fine-tuning?

This is the clearest case for B200 in fine-tuning: when a base model is too large for even H200's 141GB to handle with QLoRA, it becomes realistic on a single B200's 192GB, avoiding a multi-GPU setup entirely.

Q3
Do fine-tuning frameworks support B200?

Hugging Face PEFT and Axolotl both support B200, since it's a supported Blackwell-generation card for these frameworks. No changes to your fine-tuning setup are needed moving from H100 or H200.

Q4
Should I default to H100, H200 or B200 for fine-tuning?

H100 or H200, for the large majority of fine-tuning work. B200's premium only pays off when your specific base model size genuinely requires more than 141GB, which is uncommon for typical fine-tuning projects.

Q5
Is B200 harder to find for fine-tuning workloads specifically?

In several markets, yes, given the liquid cooling and power infrastructure B200 requires. For typical fine-tuning work that doesn't need B200's extra memory anyway, this availability gap is one more reason H100 or H200 remains the simpler choice.

Q6
What's the real NVIDIA B200 rental rate for fine-tuning work?

B200 median on-demand rate runs $6.01/hr, a real premium over H100's $3.33/hr and H200's $4.40/hr median. NVIDIA B200 rental pricing through GPUaaS.com is quoted per enquiry and varies by commitment term, configuration and placement.