Blog ▸ From Cost Centre to Revenue Line: How Enterprises Are Rethinking Owned GPU Infrastructure
GPU Infrastructure
A GB200 NVL72 rack can generate $18,000 to $28,000 a day in compute revenue, most of which enterprises never collect. Here is how leading organizations are rethinking owned GPU infrastructure.
From Cost Centre to Revenue Line: How Enterprises Are Rethinking Owned GPU Infrastructure
GPUaaS.com Team
GPU Infrastructure
July 28, 2026
No items found.
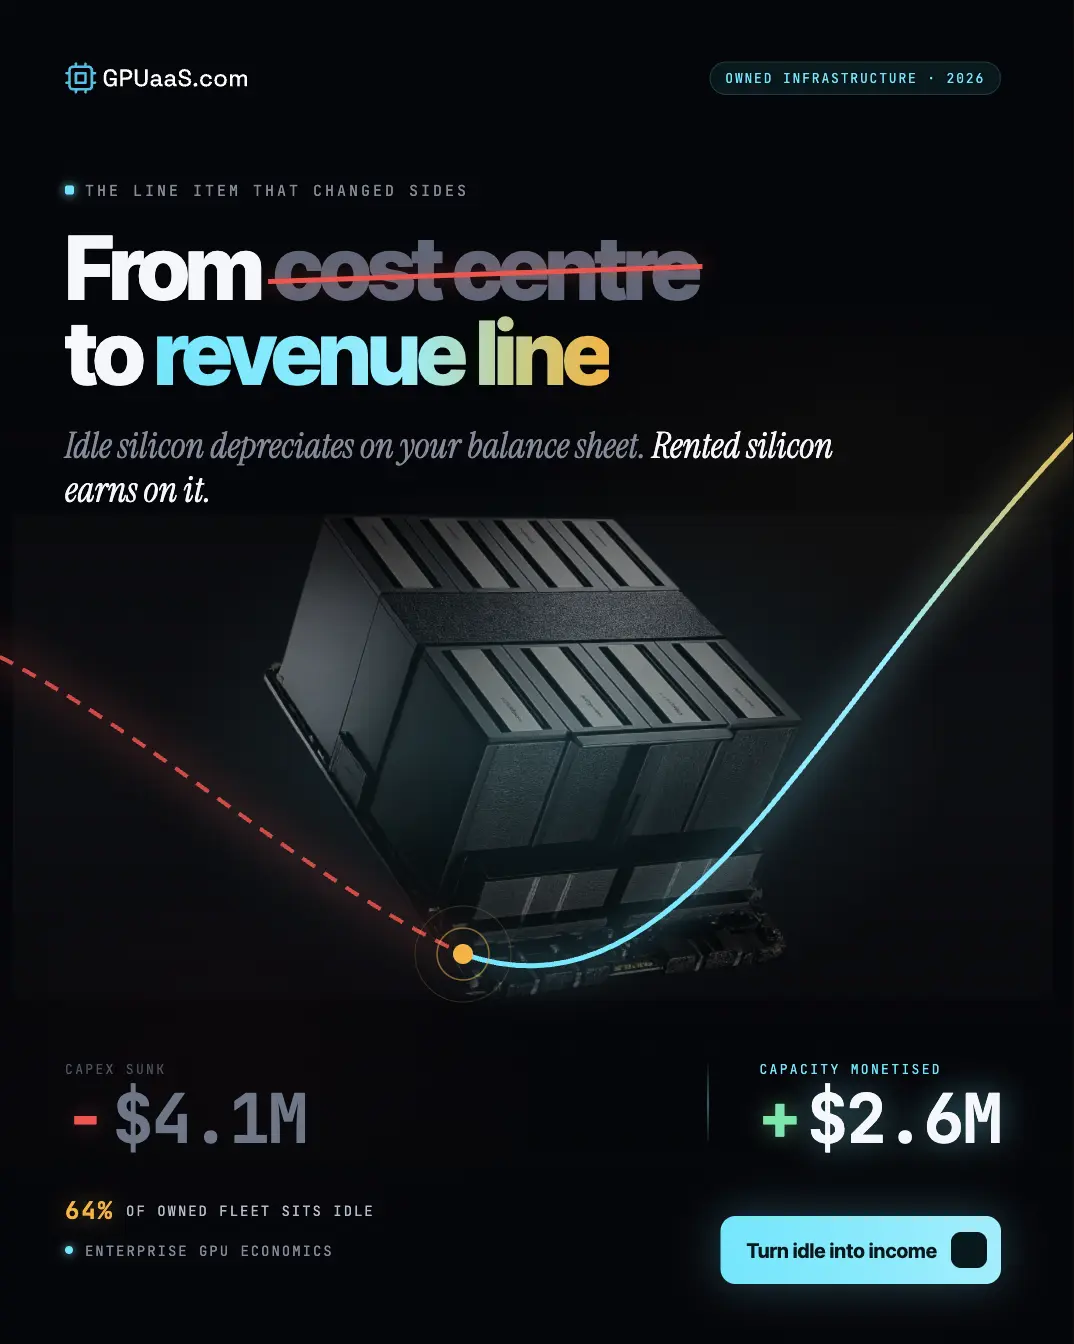
A 1,024-GPU H100 cluster running at 55% utilization loses roughly $330,000 a month. The same cluster at 85% utilization earns roughly $340,000 a month. Same hardware, same power bill, same depreciation schedule. A 30-point utilization swing is the entire difference between a $330K monthly loss and a $340K monthly gain.
Standard accounting treats a GPU cluster as pure cost. Capex on the balance sheet. Depreciation running against it. Power and cooling on top. That framing misses the part that actually determines whether the asset makes or loses money.
Key takeaways
A 1,024-GPU H100 cluster loses ~$330K/month at 55% utilization and earns ~$340K/month at 85%. The breakeven point for a debt-financed cluster sits around 70% utilization
A GB200 NVL72 rack can generate $18,000 to $28,000/day in on-demand compute revenue, revenue most owners never collect
Average enterprise GPU utilization sits at 5% across 23,000 measured production clusters (Cast AI, 2026), while two-thirds of enterprises report peak utilization below 70%
Chargeback or showback, billing internal teams for the GPU capacity they actually consume, changes behavior even before any external monetization happens
Enterprises shifting from cost-centre to revenue-line thinking aren't buying fewer GPUs, they're offering unbooked windows to external buyers instead of leaving them idle
◆ THE 30-POINT SWING
Where the loss becomes a gain
A debt-financed GPU cluster breaks even at roughly 70% utilization. Below that line, every idle GPU-hour is depreciating and accruing interest without generating anything against either cost. Above it, the same hardware, financed the same way, running the same power draw, starts producing real margin. Gross margins on bare-metal GPU capacity typically run 55 to 65% before depreciation is even factored in, which leaves almost no room to absorb idle time once the debt service and operating costs are counted.
That's the part standard cost-centre accounting doesn't show. A GPU cluster sitting at 5% utilization isn't just "underused." It's actively bleeding against the breakeven point every single hour, in a way a simple capex-and-depreciation line item never surfaces to whoever's actually reviewing the budget.
◆ NEO-REAL ESTATE, NOT NEO-CLOUD
5% average utilization across 23,000 clusters
Cast AI's 2026 measurement across 23,000 production clusters found average enterprise GPU utilization at 5%. Cast AI's co-founder named what many fleets have become. Not cloud infrastructure. Neo-real estate. A separate industry survey found two-thirds of enterprises report peak GPU utilization below 70%, meaning even at the single busiest moment of the day, most fleets never even touch the point where a debt-financed cluster breaks even.
◆ THE FIRST STEP: MAKING USAGE VISIBLE INTERNALLY
Chargeback and showback, before any external monetization
Before an enterprise even considers offering idle capacity externally, the more common first step is making internal usage visible. Assigning AI infrastructure costs to the specific business units consuming it creates accountability that a shared infrastructure pool rarely has on its own. Even showback, giving teams visibility into what they're consuming without actually billing them for it internally, changes behavior simply by making consumption visible to the people using it.
Hard allocation limits per team, combined with queue-based scheduling for non-urgent workloads, prevent any single team or model from monopolizing shared infrastructure indefinitely. This isn't about slowing anyone down. It removes the incentive teams currently have to over-provision as a hedge against not getting capacity later, which is exactly the dynamic that produces a fleet running at 5% utilization in the first place.
◆ A LEASABLE ASSET, NOT A SUNK COST
What external monetization actually looks like
Once internal allocation is under control, the enterprises going further aren't buying fewer GPUs. They're treating owned hardware as a leasable asset rather than a fixed cost. A rack not fully booked for internal work during a specific window gets offered to a vetted external buyer for that window specifically, not indefinitely. Capacity returns to internal use the moment it's actually needed again.
This is closer to how a landlord thinks about an office building's unused floors than how a traditional IT department thinks about a server room. The asset stays owned. The utilization schedule around it becomes something actively managed rather than something that just happens.
$18K-$28K
the daily on-demand compute revenue a single GB200 NVL72 rack can generate, revenue most owners never collect
Source: American Compute 2026, cited in ModulEdge's Neocloud unit economics analysis
GPU rental rates on the exact hardware most enterprises already own run a few dollars an hour to well over ten, depending on chip generation and demand. Multiply that by the hours a rack sits idle in a typical month. The uncollected revenue on a rack at 5% utilization is not a rounding error, and once a cluster's actual breakeven point is known, the size of the gap becomes a specific number rather than a vague sense that something is being wasted.
The same scarcity pressure that drove overbuying is why nobody releases capacity back, even capacity sitting unused. Procurement and runtime get managed as two separate problems, usually by two different teams reporting up two different chains. They're one problem from two ends. A procurement decision made under scarcity pressure creates the idle capacity that shows up on a utilization dashboard months later, and the team looking at that dashboard rarely has any input into the original purchase decision.
A rack stays available for internal use the moment it's needed. Still owned. Still on the balance sheet. What changes is whether the idle hours sit unused or get offered against real external demand, and whether the utilization number itself becomes something finance and infrastructure teams review together instead of something only engineering ever looks at.
See what your idle hours are worth right now.
Submit cluster availability, get matched with vetted buyers. For single-GPU or month-to-month demand, packet.ai handles self-serve access with 24/7 human support.
Roughly 70% for a debt-financed cluster, per American Compute's 2026 analysis. On a real 1,024-GPU H100 cluster, 55% utilization produces a loss of roughly $330,000 a month, while 85% utilization produces a gain of roughly $340,000 a month, illustrating how directly utilization drives the underlying economics.
A single GB200 NVL72 rack can generate $18,000 to $28,000 a day in on-demand compute revenue. At 5% average utilization, the large majority of that daily figure goes uncollected on a rack that's fully owned and paid for, sitting idle rather than earning against its own capacity.
Chargeback bills internal teams for the GPU capacity they actually consume. Showback gives teams visibility into their consumption without billing them internally. Both create accountability that a shared, unmetered infrastructure pool typically lacks, and both are usually the first practical step before an enterprise considers monetizing idle capacity externally.
No. Availability windows are set by the owner, and capacity returns to internal use the moment it's needed. External use only applies to hours the owner has designated as unbooked for internal work, similar to how a landlord leases only the space that's genuinely unused rather than the whole building.
Submit cluster availability, GPU tier, count, available hours, region, through GPUaaS.com, and get matched with vetted buyers looking for exactly this kind of capacity.
Last reviewed: 14 August 2026. Utilization data from Cast AI's 2026 State of Kubernetes Optimization Report, 23,000 clusters. Rack-level revenue data from ProphetStor's GPU Infrastructure Yield Layer analysis, 2026. Utilization breakeven and cluster economics from American Compute's 2026 GPU cloud economics data, via ModulEdge's Neocloud unit economics analysis. Chargeback and showback governance patterns from V2 Solutions' Idle GPUs in Enterprise AI Platforms report. Peak utilization survey data from the State of AI Infrastructure at Scale 2026 report. List your idle GPU cluster on GPUaaS.com.