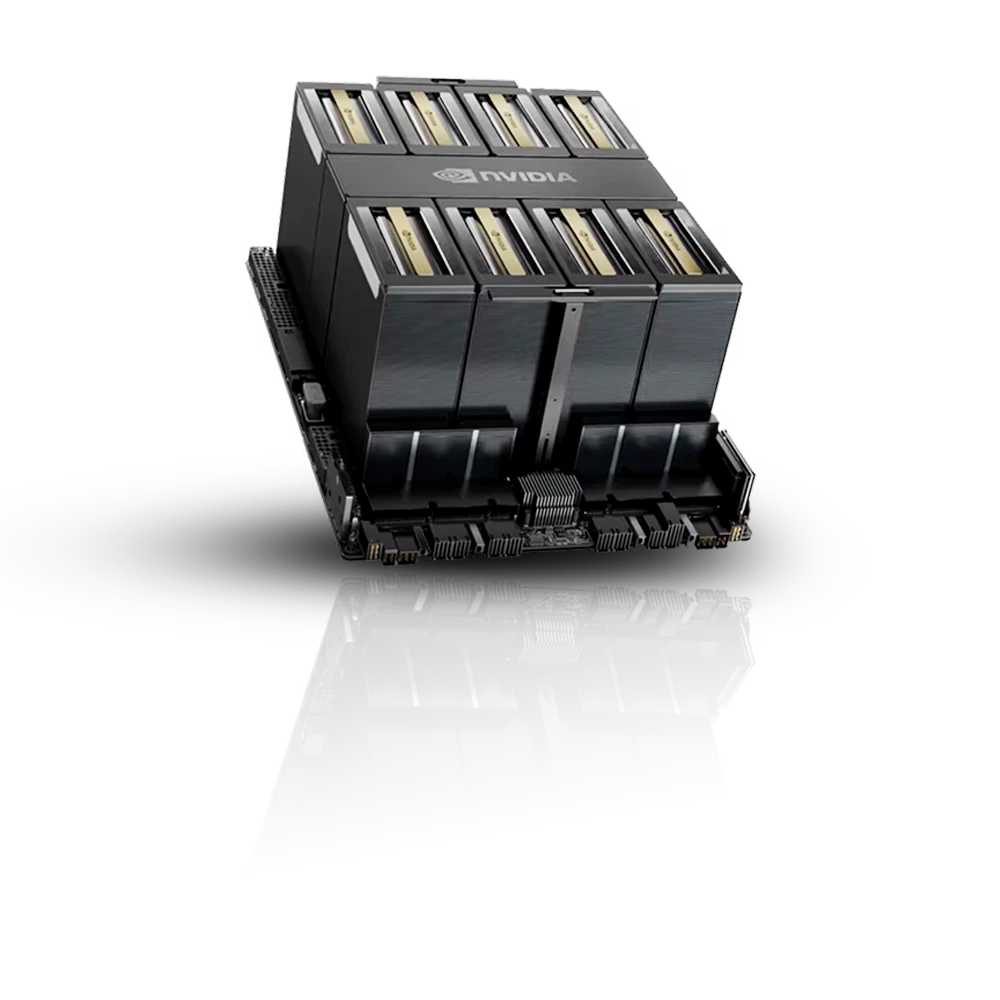
Cost per token is the hourly rate divided by sustained throughput, and for Vera Rubin neither number is settled yet. Tracked early-access pricing starts around $11.00/hr on reservation terms in a very thin market, and the throughput you will actually get on a new generation depends on your model, precision and a serving stack still maturing for it. Vendor figures are a starting point, not a substitute for measuring your own workload. Vera Rubin NVL72 offers 288GB of HBM4 per GPU at 22TB/s across 72 GPUs in one NVLink 6 domain, which can change the serving topology for the largest models, but only if you can keep a rack busy. Register interest and we will confirm what is securable. GB300 cost per token, B300 and B200 are the measurable comparison points today.
Vera Rubin's cost per token is driven by four levers more than by the headline rate: how fully you utilise a rack contracted as 72 GPUs, whether rack-scale memory and HBM4 bandwidth remove sharding overhead a smaller cluster would pay, how mature the serving stack is on a new generation, and the commercial term. Against GB300, the same rack-scale design available now at a lower and more widely quoted rate, Vera Rubin only wins on cost per token if its extra memory bandwidth and rack scale change what you can serve per rack. Early-access rates come from a very thin set of providers and are directional, and vendor throughput figures are no substitute for measuring your own workload. For anything that fits on GB300, B300 or B200, the lower and better-understood rate usually wins today.
Vera Rubin economics depend on placement and terms, and supply is still forming: confirm real in-country availability and rates in a quote. See Vera Rubin availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


