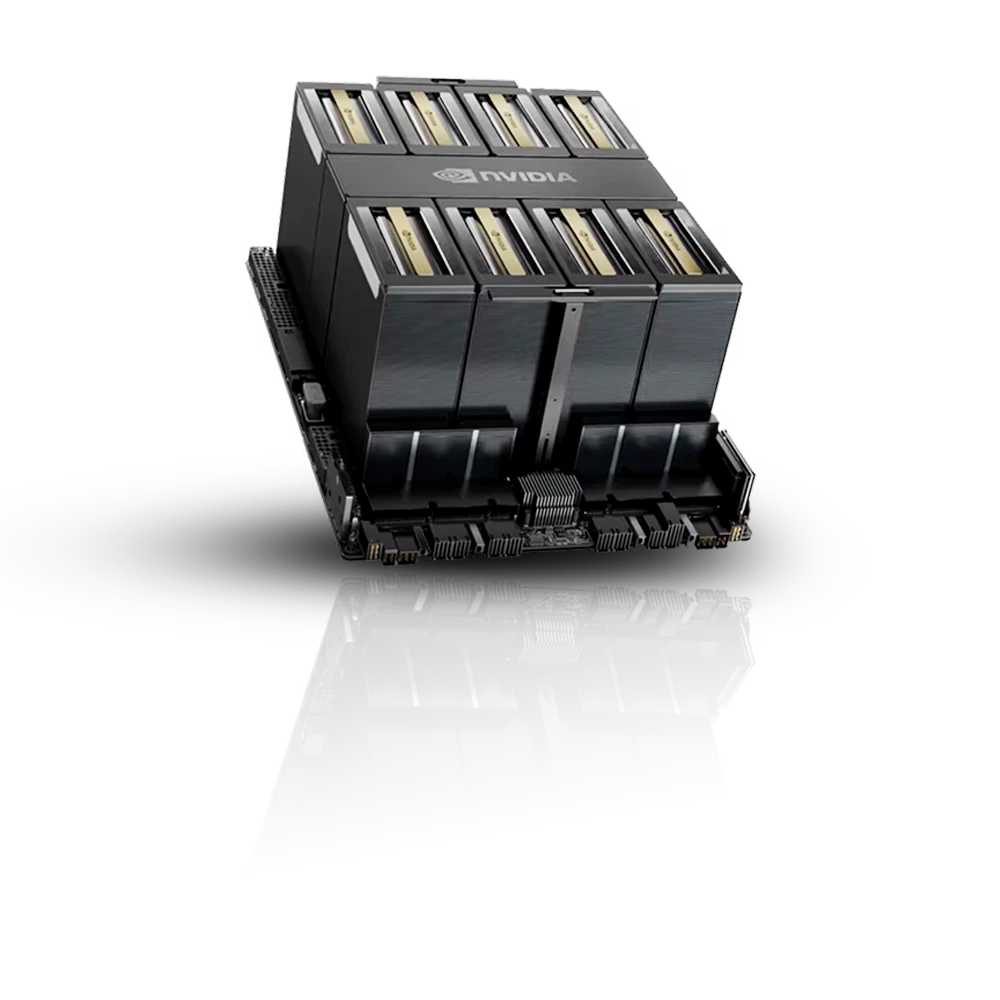
RTX PRO 6000 is the card that puts 70B-class inference on a single GPU at a mid-range price. Its 96GB of GDDR7 ECC at up to 1.79TB/s fits Llama 3.3 70B at FP8 with KV cache headroom, or roughly 146B parameters at 4-bit quantization. That is more memory than H100's 80GB at a lower hourly rate, with a tracked median near $2.20/hr across 40+ providers against $3.33/hr for H100. It is PCIe-only with no NVLink, so it suits single-GPU serving and independent replicas rather than models that must span cards. Full RTX PRO 6000 specs are available on request. RTX 5090 for LLM inference is the lower-cost option for models that fit in 32GB, and H100 and H200 are the step up for multi-GPU serving.
RTX PRO 6000 earns its place in inference through memory at a mid-range price. 96GB of GDDR7 ECC at up to 1.79TB/s fits Llama 3.3 70B at FP8 with room for KV cache, or roughly 146B parameters at 4-bit, which puts 70B-class serving on a single card at a tracked median near $2.20/hr. MIG adds hardware partitioning for serving several models or tenants on one GPU. The limit is interconnect: the card is PCIe-only with no NVLink, so serving that has to span several GPUs belongs on H100 or H200, and models that fit in 32GB are cheaper on RTX 5090. RTX PRO 6000 is offered as a Server Edition built for datacenter racks and as Workstation editions, so confirm the edition and its terms with the operator.
RTX PRO 6000 capacity is confirmed across major clouds and specialist providers in many markets. Confirm the operator and edition for your location. See RTX PRO 6000 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


