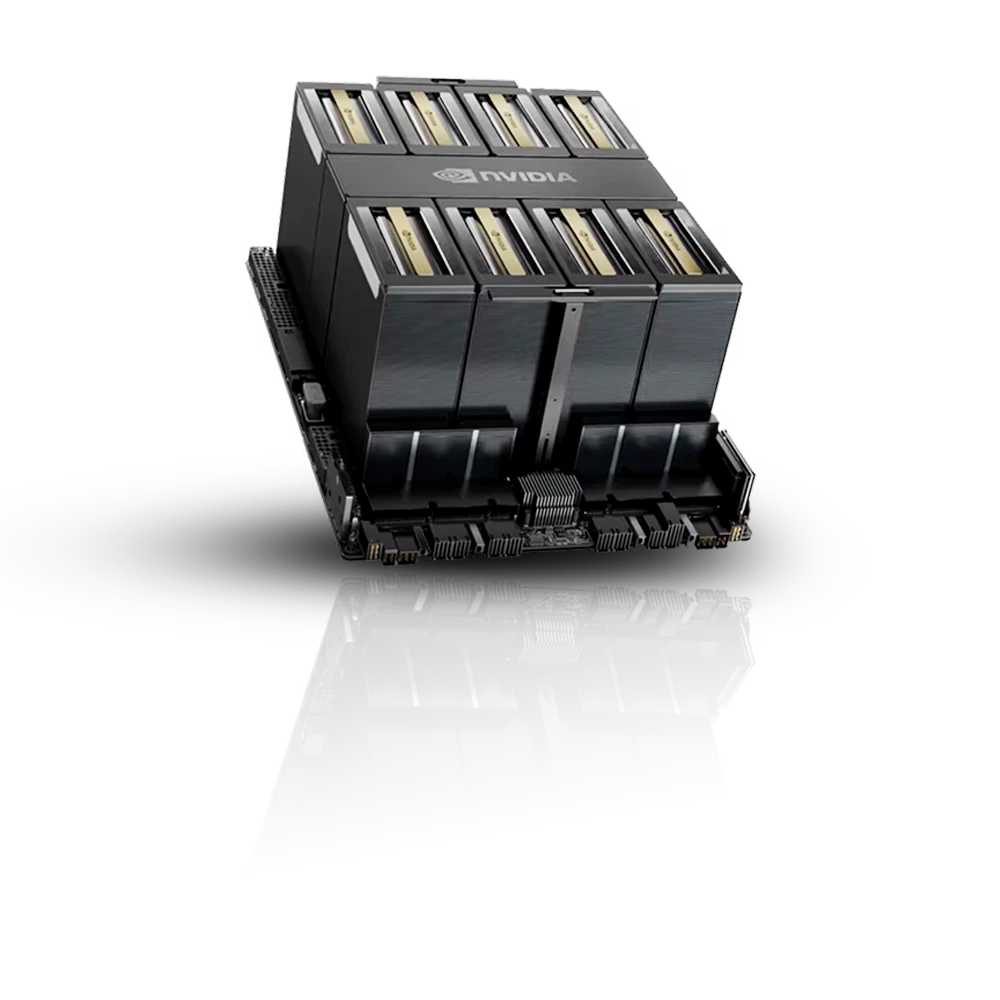
Image generation is more compute-bound than memory-bound for typical resolutions, so H200's identical compute to H100 means most single-image generation workloads see no speed difference between the two. Where H200 genuinely helps is scale: 141GB lets a production pipeline batch more images per generation pass, run larger or multiple diffusion models simultaneously, or push to higher resolutions without hitting memory limits mid-batch. For a team generating images at high volume with heavy batching, or fine-tuning larger custom models with LoRA or DreamBooth, H200's extra headroom translates into fewer memory-related bottlenecks. H100 for image generation handles typical single-model batch generation just as well at a lower hourly rate, B200 for the very highest-volume production services, and B300 further still for the largest-scale production needs. GB300 for image generation sits at the top of the range as rack-scale Blackwell Ultra for the largest workloads.
Image generation with diffusion models is predominantly compute-bound for typical single-image workloads, meaning H200's identical compute to H100 produces no meaningful speed difference at standard batch sizes and resolutions. The case for H200 changes specifically at production scale: 141GB of HBM3e lets a batch of many images process together in one generation pass, or lets a service run several diffusion models simultaneously, both of which H100's 80GB would constrain. For teams fine-tuning custom styles across multiple base models or fine-tuning larger diffusion models via LoRA or DreamBooth, H200's extra headroom similarly removes a memory ceiling that would otherwise force splitting jobs across cards. The practical guidance is straightforward: H100 for typical generation workloads, H200 specifically when batch size, model count, or model size pushes against 80GB.
Image generation workloads are often bursty, so being able to place capacity close to where demand actually happens matters. See H200 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


