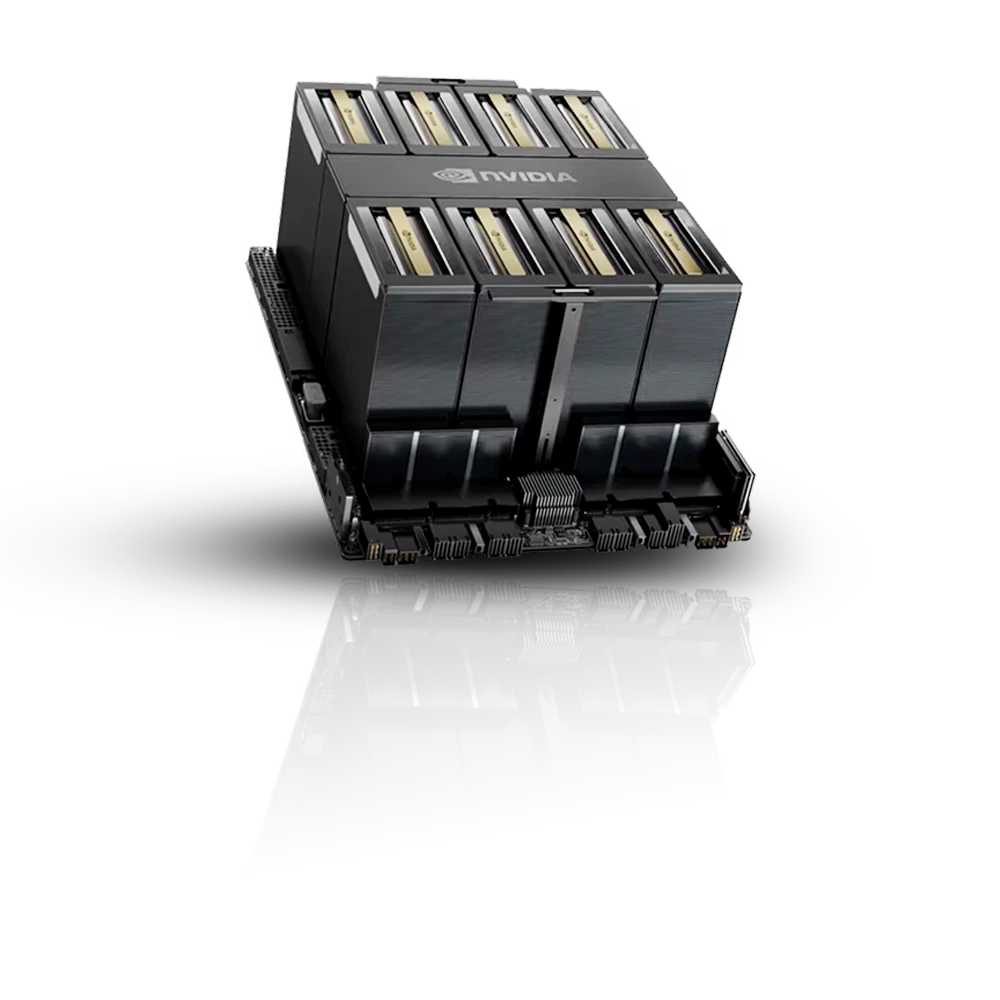
Diffusion models like Stable Diffusion and Flux generate images through an iterative denoising process, running the same network many times per image rather than once, which makes raw compute throughput matter more here than it does for most LLM inference. H100's FP8 and BF16 throughput lets it batch multiple generations simultaneously, and 80GB of HBM3 gives headroom to run larger models, higher resolutions, and bigger batches without hitting memory limits. Best GPU for image generation is one of the few usecase-level searches with real, if modest, search volume, and H100 shows up as a common answer precisely because it handles both high-volume batch generation and the fine-tuning of custom models (via LoRA or DreamBooth) on the same card. H200, B200 and B300 for image generation are worth the premium specifically at higher production scale. GB300 for image generation sits at the top of the range as rack-scale Blackwell Ultra for the largest workloads.
Image generation with diffusion models is compute-bound in a way that differs from LLM inference: each image requires dozens of denoising steps through the full network, so throughput per step matters more than memory bandwidth alone. H100's FP8 support and high FLOPS throughput let it process these steps faster than the previous generation, and batching multiple image requests together (processing several images' worth of denoising steps in parallel) is where H100's compute advantage compounds. For teams that also fine-tune custom styles or subjects into a diffusion model, using techniques like LoRA or DreamBooth, the same 80GB of HBM3 that helps with LLM fine-tuning applies here too, letting a custom model be trained without needing a specialized setup.
Image generation workloads are often bursty, so being able to place capacity close to where demand actually happens matters. See H100 availability by country below.
Read the full guide to GPU cloud in this location →Every location links to its own page. Click through for local pricing and specs.
Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
—
Need a different GPU generation? Each model available here has a dedicated page with full pricing and specifications.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.
GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


