RTX 5090
USA
{"@context":"https://schema.org","@graph":[{"@type":"Service","@id":"https://gpuaas.com/gpu/rtx-5090-usa#service","name":"RTX 5090 in the USA","provider":{"@type":"Organization","name":"GPUaaS.com","url":"https://gpuaas.com"},"areaServed":{"@type":"Country","name":"USA"},"serviceType":"GPU cloud infrastructure","description":"Rent NVIDIA RTX 5090 GPU cloud capacity in the USA, the deepest confirmed market for this card. 32GB GDDR7, cloud pricing from $0.27/hr."},{"@type":"WebPage","@id":"https://gpuaas.com/gpu/rtx-5090-usa#webpage","url":"https://gpuaas.com/gpu/rtx-5090-usa","name":"RTX 5090 in the USA","isPartOf":{"@type":"WebSite","name":"GPUaaS.com","url":"https://gpuaas.com"}},{"@type":"BreadcrumbList","@id":"https://gpuaas.com/gpu/rtx-5090-usa#breadcrumb","itemListElement":[{"@type":"ListItem","position":1,"name":"Home","item":"https://gpuaas.com"},{"@type":"ListItem","position":2,"name":"GPU Cloud in the USA","item":"https://gpuaas.com/gpu-cloud/usa"},{"@type":"ListItem","position":3,"name":"RTX 5090 in the USA","item":"https://gpuaas.com/gpu/rtx-5090-usa"}]},{"@type":"FAQPage","@id":"https://gpuaas.com/gpu/rtx-5090-usa#faq","mainEntity":[{"@type":"Question","name":"Can I rent an RTX 5090 in the USA?","acceptedAnswer":{"@type":"Answer","text":"Yes, and the USA has the deepest confirmed RTX 5090 provider set globally: Spheron, CloudRift, RunPod, Lambda, SaladCloud and several others all list US-based capacity today."}},{"@type":"Question","name":"What is the RTX 5090 price per hour in the USA?","acceptedAnswer":{"@type":"Answer","text":"RTX 5090 price and pricing globally runs from roughly $0.27/hr at the cheapest verified providers to $0.99/hr, with a median around $0.65–$0.80/hr across 20+ tracked providers, most of them US-based."}},{"@type":"Question","name":"What are the RTX 5090 specs?","acceptedAnswer":{"@type":"Answer","text":"32GB VRAM (GDDR7) on a 512-bit bus, 1.79TB/s bandwidth, 575W TDP, 21,760 CUDA cores, Blackwell architecture with 5th-gen Tensor Cores and FP4 support. Launched 30 January 2025."}},{"@type":"Question","name":"Is the RTX 5090 suitable for AI and LLM workloads?","acceptedAnswer":{"@type":"Answer","text":"Yes, RTX 5090 for AI and LLM inference fits models up to roughly 41B parameters at 4-bit quantization or 9B at 16-bit within its 32GB VRAM. It's strong for LoRA/QLoRA fine-tuning, Stable Diffusion inference, and local LLM serving."}},{"@type":"Question","name":"RTX 5090 vs H100 vs RTX 6000 Pro: which should I rent in the USA?","acceptedAnswer":{"@type":"Answer","text":"RTX 5090 vs H100: RTX 5090 is far cheaper per hour and suits single-GPU inference, fine-tuning, and development work. RTX 5090 vs RTX 6000 Pro comes down to VRAM: 32GB against 96GB, so the Pro card fits larger single-GPU models."}},{"@type":"Question","name":"What compliance can US RTX 5090 placement satisfy?","acceptedAnswer":{"@type":"Answer","text":"FedRAMP-aligned hosting, ITAR-adjacent handling, and HIPAA-compatible controls, depending on operator identity and access controls, the same as for datacenter-class generations on this site."}}]}]}
GPUAAS.COM · WHOLESALE GPU NETWORK / A HOSTED·AI SERVICE ◆ CAPACITY AVAILABLE · 20+ PARTNERSQUOTES < 24HREV 2026.09
+
+
RTX 5090 32GB VRAM in the USA
◆ AVAILABLE

RTX 5090
in the USA
, at
wholesale price.

RTX 5090 quotes for US teams, sourced from vetted single-GPU and small-cluster operators, at
~30% less than hyperscale. Quotes in under 24 hours.

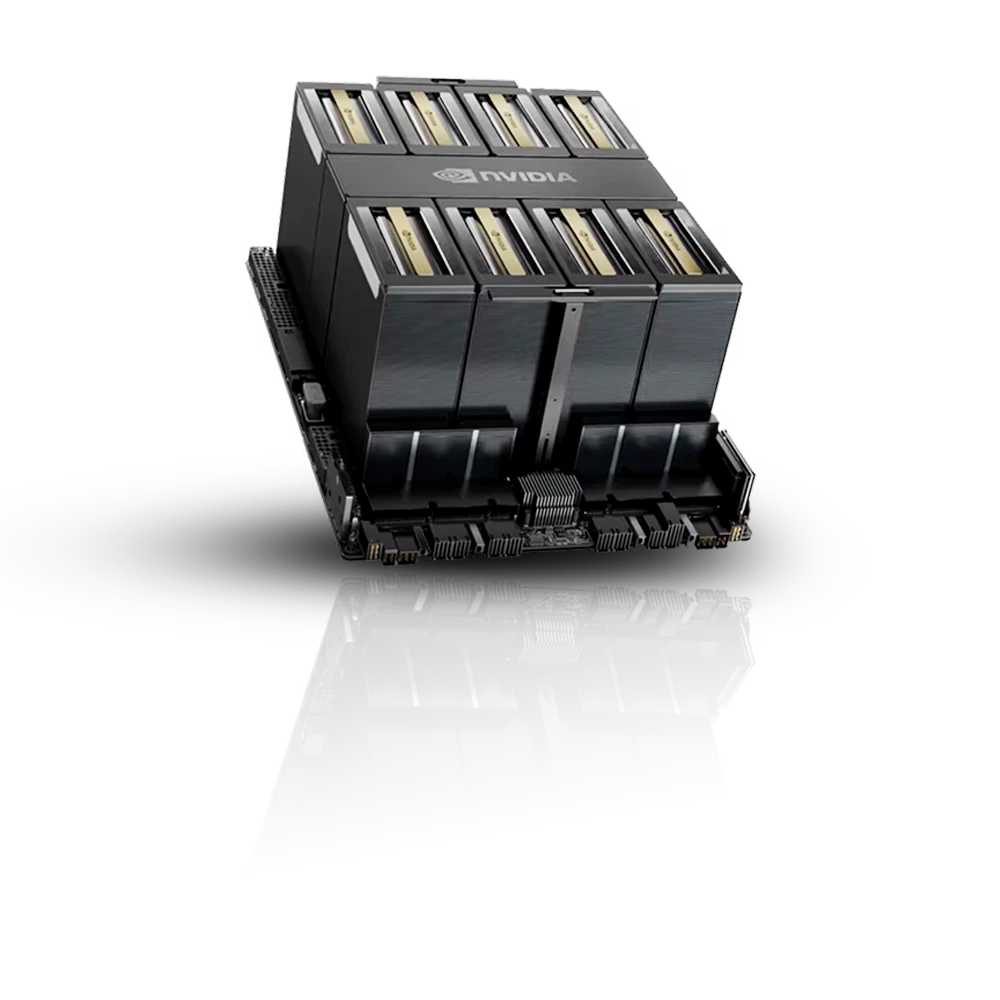
HGX GPU node
GPU generations
4
Architectures
Hopper + Blackwell
Vetted partners
20+
Quote turnaround
24 hrs
Commitment
Short / long
QUOTES IN UNDER 24 HOURS VETTED PARTNERS WORLDWIDE SHORT OR LONG TERM COMMITMENT DIRECT OPERATOR CONTRACTS CAPACITY AVAILABLE NOW PLACEMENT YOU SPECIFY
◆ THE SHORT ANSWER

Yes. NVIDIA RTX 5090 capacity is confirmed available in the USA, the strongest market for this card globally. Spheron lists RTX 5090 deployment across data center partners in "North America, Europe, and Canada," and consumer/prosumer-focused providers including CloudRift, RunPod, Lambda and SaladCloud run US-based capacity today. The RTX 5090 is a consumer/workstation Blackwell card, not a rack-scale datacenter part: 32GB GDDR7 memory, 1.79TB/s bandwidth, 575W TDP, launched 30 January 2025. Global cloud pricing runs from roughly $0.27/hr at the cheapest verified providers up to $0.99/hr, with a median around $0.65–$0.80/hr. For rack-scale training or multi-GPU inference, H100 and B200 in the USA remain the better fit.

+
01
◆ PRICING

RTX 5090 price and pricing per hour in the USA

RTX 5090 price and pricing here reflects the tracked global market: cheapest verified rate is $0.27/hr, median across 20+ providers runs $0.65–$0.80/hr, and the USA has the deepest confirmed footprint of any market.

Market reference as of September 2026, quoted in USD. RTX 5090 is a widely-tracked consumer/prosumer card with over 20 providers globally, and the USA has the deepest confirmed provider footprint of any market.
Wholesale rates through GPUaaS.com are quoted per enquiry and vary by commitment term, configuration and placement.

$0$2.50$5$7.50$10$12.50$15/GPU-HR
Cheapest verified on-demand
Global tracked low, Vast.ai
$0.27
Market median (20+ providers)
Global on-demand median
$0.70
Reserved / longer-term
Lower end, monthly commitment
~$0.21
Higher-end on-demand
Upper end, lower-capacity providers
~$0.99
◆ GPUaaS.com wholesale
Vetted partners · direct operator contract
quoted per enquiry
◆ RTX 5090 RATES VARY BY TERM, CONFIGURATION AND PLACEMENT
+
02
Where a US RTX 5090 earns its keep

The workloads a US RTX 5090 is built for.

The USA has the deepest confirmed RTX 5090 provider set of any market: Spheron, CloudRift, RunPod, Lambda, SaladCloud, HyperAI, Vast.ai and GPU.ai all list US-based capacity, several with same-day deployment. This is the card's home market by volume, and pricing here typically sits at or below the global median given the density of competing providers.

/01

RTX 5090 LLM inference

Serve 7B–13B quantized models with real headroom, from the deepest RTX 5090 provider footprint of any market.
32GB GDDR7 · FP4 · vLLM
/02

LoRA and QLoRA fine-tuning

Rent an RTX 5090 to fine-tune 7B–13B models with same-day US deployment through several confirmed providers.
Blackwell · 5th-gen Tensor Cores · QLoRA
/03

Image and video generation

Faster generation and upscaling pipelines than the previous generation, at consumer-card pricing.
Stable Diffusion · Flux · 1.79TB/s bandwidth
/04

Development and prototyping

Iterate on model architecture and pipelines cheaply on a dedicated RTX 5090 server. RTX 5090 vs 4090 benchmarks show roughly 2x tokens-per-second for high-concurrency serving.
RTX 5090 vs 4090 · low cost · fast iteration
+
03
◆ LIVE NETWORK · 12 LOCATIONS

Vetted GPU partners worldwide, tracking RTX 5090 availability.

RTX 5090 is available through 20+ tracked global providers, with the deepest confirmed footprint in the USA. Register interest and we will confirm what's actually available for US placement.

Read the full guide to GPU cloud in this location →
4
GPU GENERATIONS
20+
VETTED PARTNERS
12
PLACEMENT OPTIONS
24h
QUOTE TURNAROUND
USA CAN UK DEU FRA NLD UAE SAU IND SGP JPN AUS
04
◆ COST COMPARISON

See how much you save at scale

Wholesale rates against cloud list price for a 64-GPU cluster.

CLUSTER SIZE
8 GPU Servers
64 × GPUS · 730 HRS/MO
ASSUMPTIONS · BLENDED $6.00/GPU-HR · INDICATIVE ONLY
SOURCEEST. MONTHLYVS GPUAAS
Retail cloud
On-demand list price · reserved discounts require lock-in
~$280k
+$84k
Direct datacentre negotiation
Long-term commitment · slow procurement cycle
~$230k
+$34k
◆ BEST VALUE
GPUaaS.com wholesale
Vetted partners · direct operator contract · quotes in 24 hours
~$196k
SAVE ~$84k/MO
Need single-GPU compute? packet.ai has you covered.
+
05
◆ HOW IT WORKS

A matchmaker, not a marketplace.

We connect you to our vetted partners. You contract directly with the operator running your nodes.

STEP 01/4
01

Tell us the requirement

GPU model, count, placement and timeline. Add workload detail if you have it.

STEP 02/4
02

We match capacity

We find vetted partners with capacity that fits, in the jurisdiction you need.

STEP 03/4
03

Quotes in 24 hours

Real quotes from partners who hold the capacity, not listings that may not exist.

STEP 04/4
04

Contract and provision

You contract directly with the operator. We smooth the provisioning process.

Get a quote
Request wholesale rates
in under 24 hours.

Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

Quotes in under 24 hours
Direct contact with operators
Vetted partners, matched to your requirement
20+ vetted providers · 10 regions
1
ESSENTIALS
2
OPTIONAL
Contact
Full Name *
Business Email *
Organization *
Preferred Location *
Your Region *
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
GPU Requirements
GPU Model *
PRE-SELECTED
Number of GPUs *
Individual GPU count. 1 node = 8 GPUs.
Get the Best Deal
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
+
06
◆ FAQ

Frequently Asked Questions

Q1
Can I rent an RTX 5090 in the USA?

Yes, and the USA has the deepest confirmed RTX 5090 provider set globally: Spheron, CloudRift, RunPod, Lambda, SaladCloud and several others all list US-based capacity today.

Q2
What is the RTX 5090 price per hour in the USA?

RTX 5090 price and pricing globally runs from roughly $0.27/hr at the cheapest verified providers to $0.99/hr, with a median around $0.65–$0.80/hr across 20+ tracked providers, most of them US-based.

Q3
What are the RTX 5090 specs?

32GB VRAM (GDDR7) on a 512-bit bus, 1.79TB/s bandwidth, 575W TDP, 21,760 CUDA cores, Blackwell architecture with 5th-gen Tensor Cores and FP4 support. Launched 30 January 2025.

Q4
Is the RTX 5090 suitable for AI and LLM workloads?

Yes, RTX 5090 for AI and LLM inference fits models up to roughly 41B parameters at 4-bit quantization or 9B at 16-bit within its 32GB VRAM. It's strong for LoRA/QLoRA fine-tuning, Stable Diffusion inference, and local LLM serving.

Q5
RTX 5090 vs H100 vs RTX 6000 Pro: which should I rent in the USA?

RTX 5090 vs H100: RTX 5090 is far cheaper per hour and suits single-GPU inference, fine-tuning, and development work. RTX 5090 vs RTX 6000 Pro comes down to VRAM: 32GB against 96GB, so the Pro card fits larger single-GPU models.

Q6
What compliance can US RTX 5090 placement satisfy?

FedRAMP-aligned hosting, ITAR-adjacent handling, and HIPAA-compatible controls, depending on operator identity and access controls, the same as for datacenter-class generations on this site.