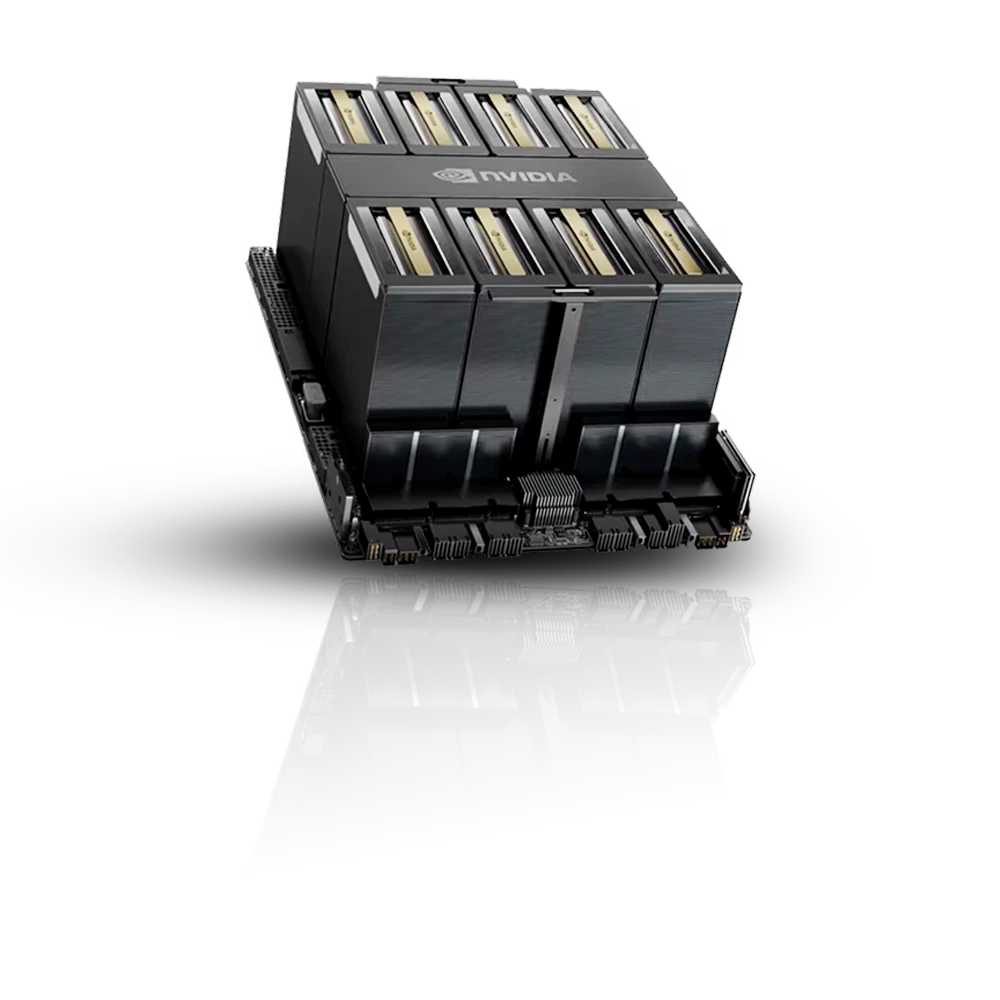
H200's real advantage for training shows up specifically in memory-bound situations: the 141GB of HBM3e over H100's 80GB means models that needed multi-GPU sharding just to fit optimizer state can often train on fewer cards, and the roughly 43% higher bandwidth speeds up the gradient and optimizer-state traffic that dominates large-batch training steps. Compute stays identical to H100, so the case for H200 in training is narrower than in inference: it earns its premium specifically when memory capacity, not raw FLOPS, is what's forcing you into a larger or more complex multi-GPU setup. H100 for LLM training remains the more cost-effective choice when your training run already fits comfortably within 80GB per GPU.
Training is dominated by memory capacity during the backward pass more than raw compute, since Adam's optimizer state alone typically needs 4x a model's parameter count in memory on top of weights, gradients and activations. H200's 141GB of HBM3e against H100's 80GB directly addresses this: models that needed sharding across two or more H100s purely to fit optimizer state, not because the compute demanded it, often train on fewer H200s instead. The roughly 43% higher memory bandwidth also speeds up the gradient and optimizer-state traffic that dominates large-batch training steps, on top of the memory-capacity benefit. Because H200 shares H100's exact Hopper compute die, the same PyTorch FSDP, DeepSpeed ZeRO or Megatron-LM setup carries over without modification, making H200 a targeted upgrade for memory-constrained training rather than a wholesale change to how a training pipeline works.
Training runs are often long-lived and data-residency sensitive, so where your cluster sits matters as much as the interconnect inside it. See H200 availability by country below.
Read the full guide to GPU cloud in this location →Wholesale rates against cloud list price for a 64-GPU cluster.
We connect you to our vetted partners. You contract directly with the operator running your nodes.
GPU model, count, placement and timeline. Add workload detail if you have it.
We find vetted partners with capacity that fits, in the jurisdiction you need.
Real quotes from partners who hold the capacity, not listings that may not exist.
You contract directly with the operator. We smooth the provisioning process.
Tell us the essentials. We'll line up real quotes from our vetted wholesale partners, and you contract directly with the operator.

GPUaaS.com connects enterprises with vetted GPU providers for large-scale compute at up to 30% lower cost than hyperscalers.


